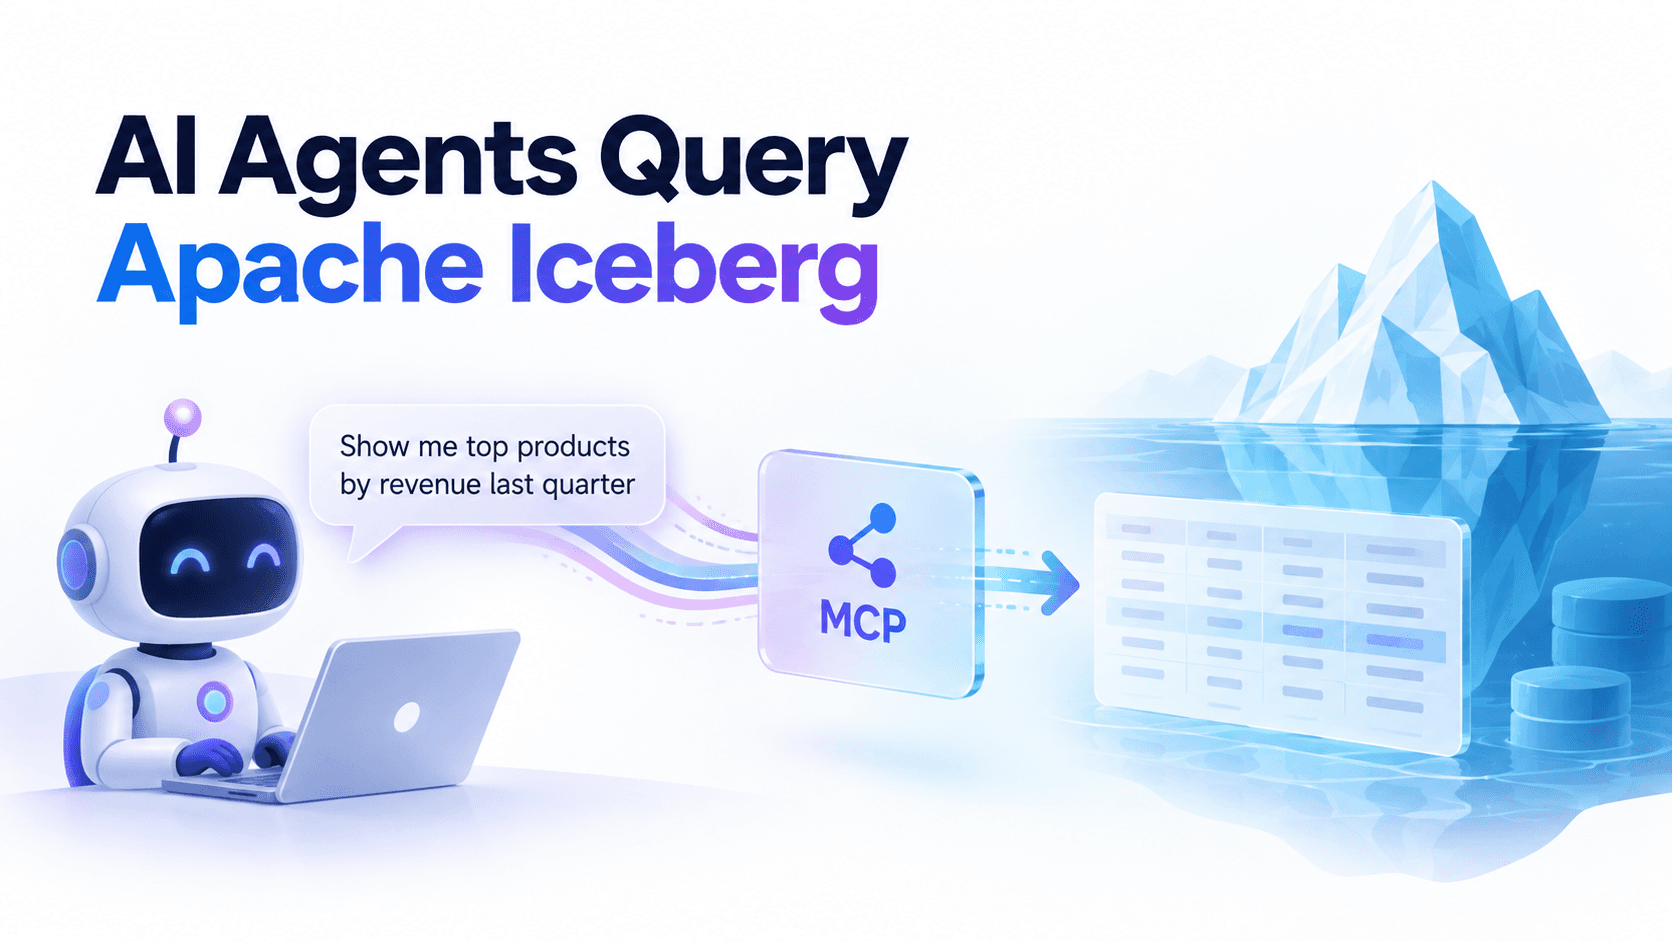
How AI Agents Query Apache Iceberg Data with MCP
A practical guide to how AI agents query Apache Iceberg tables using MCP — covering schema discovery, SQL generation, guardrails, multi-engine routing, and the control plane that ties it all together.
The converged lakehouse paradigm: combining warehouse reliability with data lake flexibility using open table formats.
89 articles

A practical guide to how AI agents query Apache Iceberg tables using MCP — covering schema discovery, SQL generation, guardrails, multi-engine routing, and the control plane that ties it all together.

AI agents querying production Iceberg tables can scan petabytes, leak PII, or drop tables — all without human review. This guide covers the guardrails, governance policies, and control plane architecture needed to give agents safe, governed access.

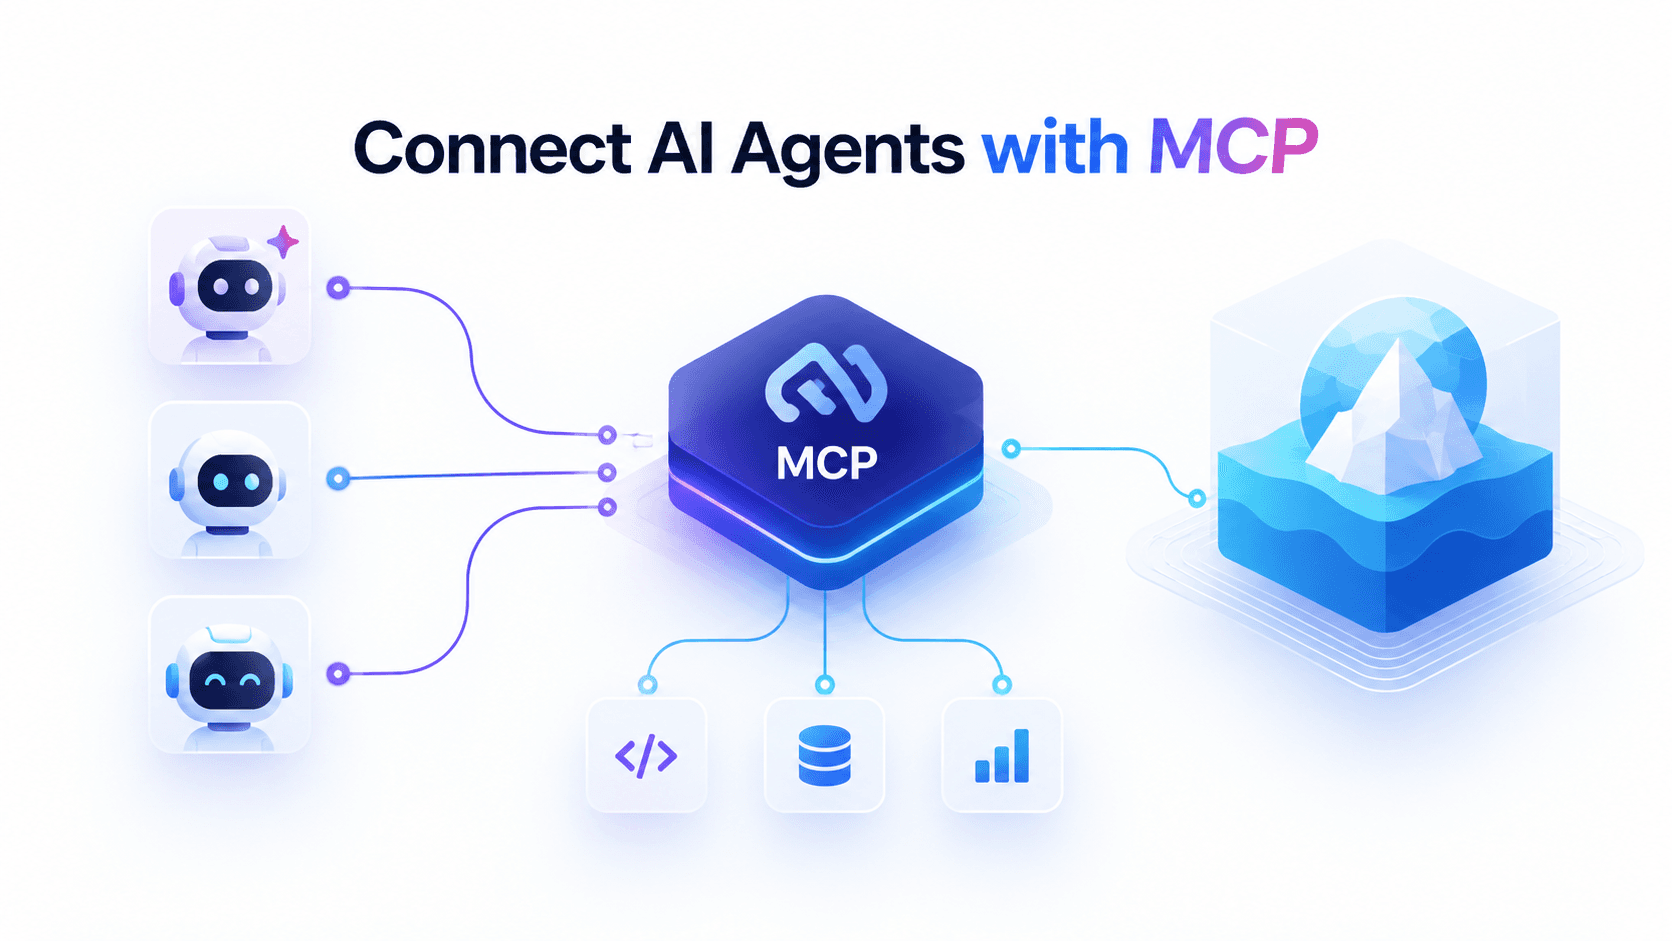
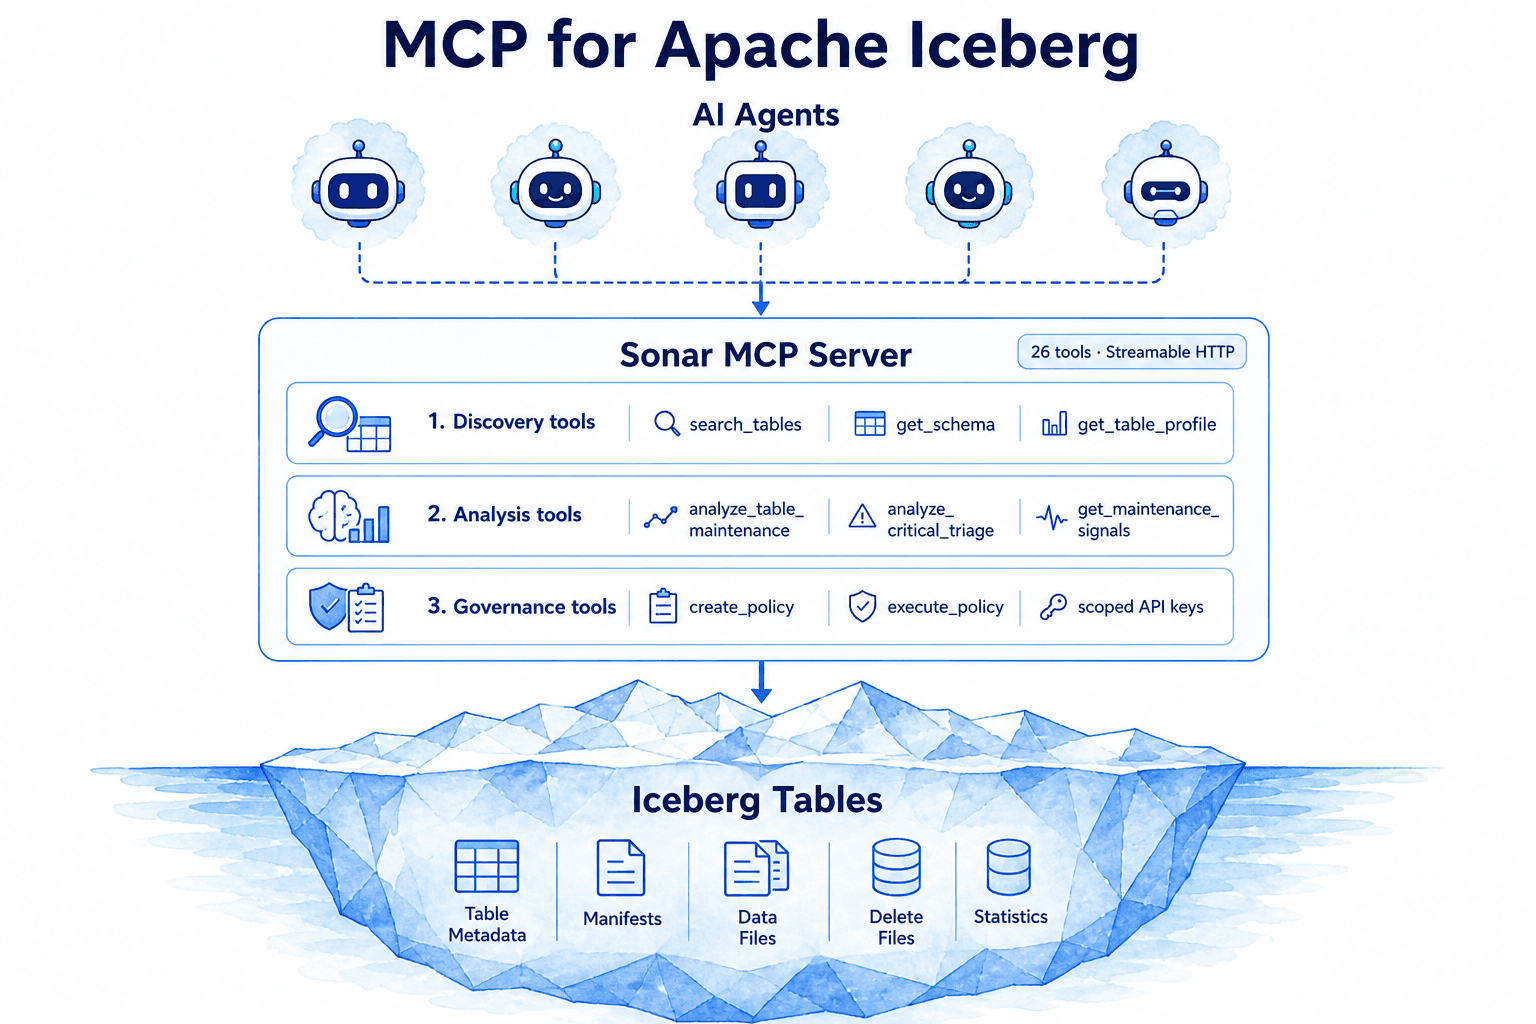
A step-by-step guide to connecting AI agents to your Apache Iceberg lakehouse using MCP and the LakeOps control plane — from API key setup to 27 auto-discovered tools for discovery, analysis, guardrails, and governance.

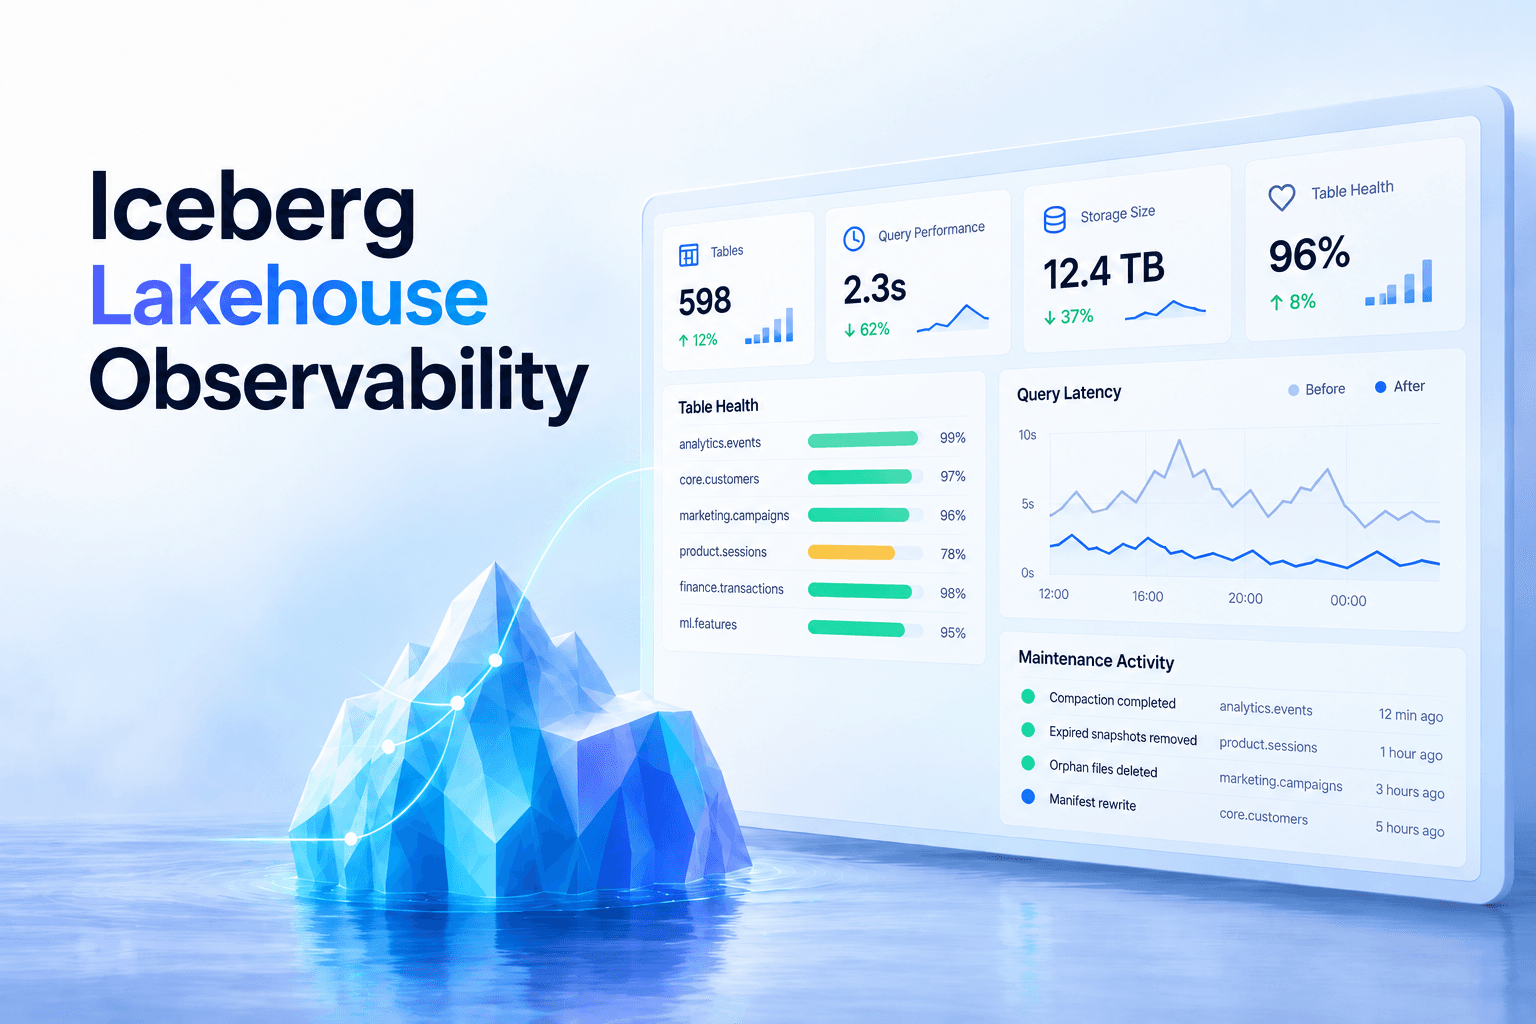
Your Iceberg lakehouse runs on open formats, multi-engine access, and decoupled storage. But without observability, every table degrades silently — files fragment, costs climb, and maintenance is guesswork. This guide covers how to build the observability layer that turns an open data lake into a managed data lakehouse.

The future of data platforms isn't one engine. It's specialized engines on shared data, and a control plane that decides where each workload runs and how the tables stay fast.

The term 'Iceberg control plane' gets used for two very different things — catalog metadata management and operational table health. This guide separates the two, explains what each layer does, and helps you choose the right architecture for a production Iceberg deployment.

The complete guide to Iceberg's rewrite_data_files procedure — strategies, parameter tuning, OOM fixes, commit conflict handling, and when to move beyond manual compaction to an automated control plane.

How a data lakehouse works in production — the four architectural layers, Iceberg's metadata tree, data flow patterns, why tables degrade under real workloads, and the closed-loop control plane that keeps the system performing at scale.

How Apache Iceberg performance actually works — the query execution pipeline, the five surfaces that degrade every production table, and the intelligent control plane that keeps file layout, sort order, metadata, and engine routing optimized continuously.

A data lakehouse control plane is the automated operational intelligence layer on top of your lakehouse infrastructure — providing full observability, governance, and control while continuously maintaining and optimizing every Iceberg table and query engine for performance and cost, without vendor lock-in.

Google engineered a multi-layered Iceberg lakehouse — autonomous storage optimization, vectorized native execution, catalog federation, and credential vending. Learn their 6-layer optimization framework and how to build the same architecture with an open, engine-neutral control plane.

Query and write Apache Iceberg tables with DuckDB — no cluster required. Catalog setup, MERGE INTO, time travel, table layout, and when to route to DuckDB vs Spark or Trino.

S3 Tables embeds managed Iceberg into S3 with automatic compaction. Self-managed Iceberg gives full control over catalogs, engines, and maintenance. A production comparison across compaction, observability, engine support, security, cost, and the control plane that ties it all together.

Getting CDC data into Iceberg is solved — Debezium, Flink, and DMS handle ingestion. The hard part is maintaining CDC tables that receive continuous updates and deletes. A practical guide to ingestion patterns, delete file management, and autonomous maintenance.

Slow Iceberg queries almost always trace back to five structural problems: small files, wrong sort order, manifest bloat, stale snapshots, or partition misalignment. This diagnostic guide shows you how to find each one, confirm it with SQL, and fix it — manually or with autonomous optimization.

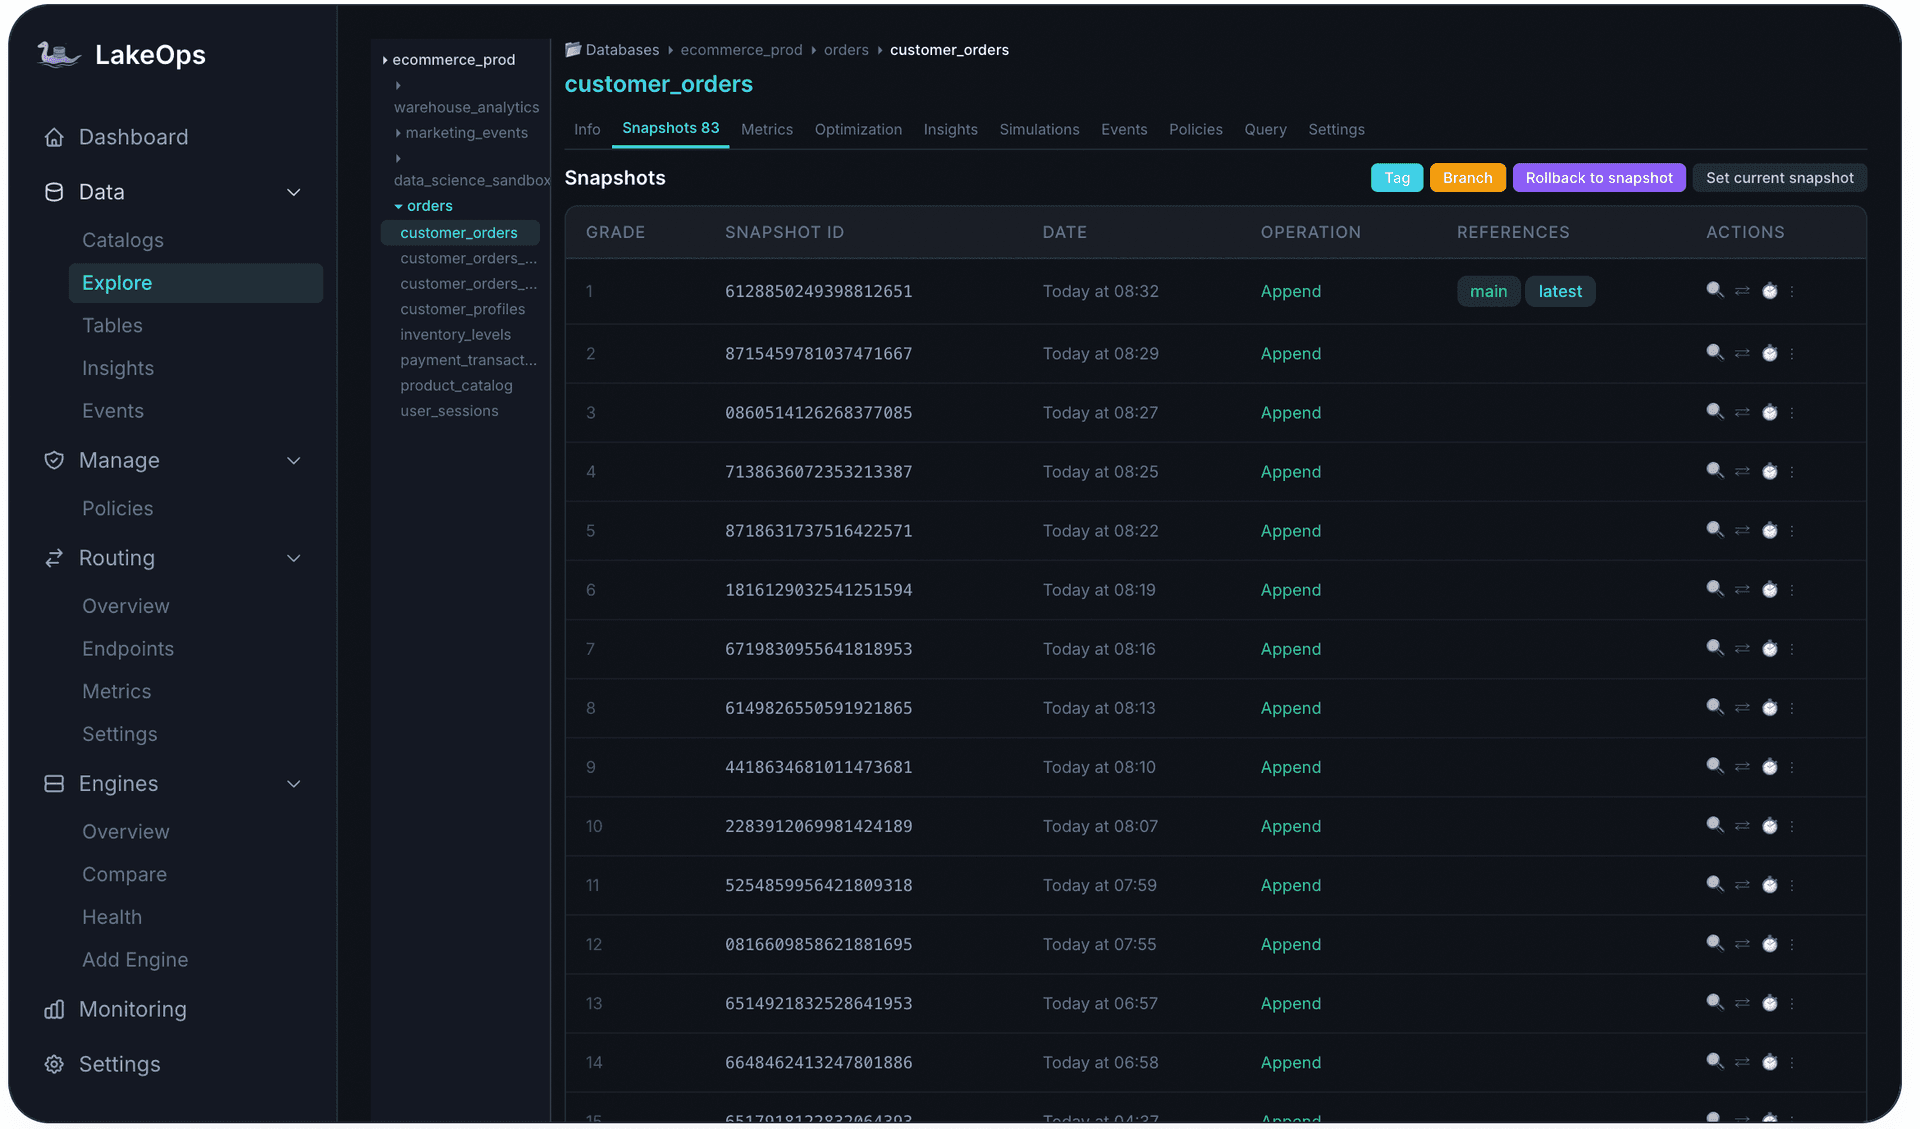
Iceberg snapshots enable time travel, rollback, and audit — but accumulate indefinitely unless managed. A practical guide to retention strategies, expiration safety, and automated lifecycle management.

A deep technical comparison of Apache Iceberg and Delta Lake across metadata, schema evolution, partitioning, engine support, and operations — and how a control plane closes Iceberg's operational gap.

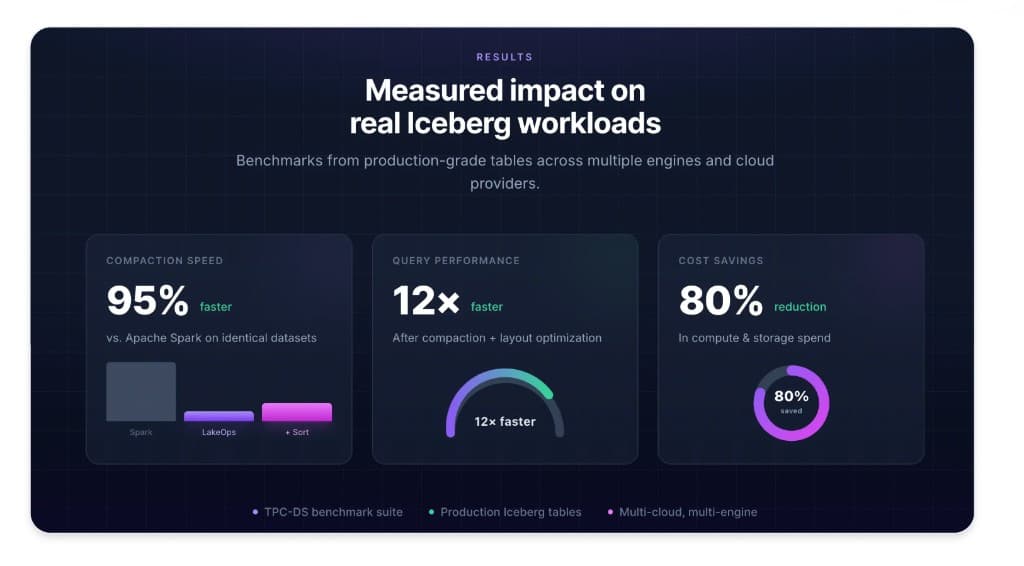
Spark compaction is expensive, slow, and architecturally wrong for file rewrites. Here's how to replace it with purpose-built engines that cost 90% less and finish 95% faster — plus the DIY path if you want to optimize what you already have.

The AI lakehouse is what happens when your data lake stops being passive storage and starts managing itself. Autonomous maintenance, query-aware compaction, multi-engine routing, continuous observability, and an agent interface layer — all working together so the lake stays healthy, fast, and ready for both human analysts and AI agents.

Data lakes without governance become data swamps — ungoverned, unobservable, and untrustworthy. This guide breaks down every pillar of production-grade lakehouse governance — policies, autonomous maintenance, observability, audit trails, lifecycle management, multi-engine control, cost governance, and AI guardrails — and shows how LakeOps delivers each as a unified control plane for Apache Iceberg.

Slow Trino queries on Apache Iceberg are rarely a compute problem — they're a table layout problem. Unmaintained Iceberg tables turn sub-second Trino scans into minute-long full reads. This guide covers seven proven fixes for faster Trino Iceberg performance: compaction, query-aware sorting, partition strategy, manifest optimization, lifecycle cleanup, multi-engine routing, and continuous observability. Why Trino-native maintenance falls short — and how to automate each fix at scale.

Your Iceberg tables are degrading right now — small files accumulating, snapshots pinning storage, manifests fragmenting — and the fix requires operational knowledge no LLM has in its weights. MCP bridges that gap. This post shows how purpose-built MCP tools turn AI agents from chat assistants into operational participants that discover, diagnose, and govern Iceberg tables with the same structured signals your best platform engineer uses.

A deep guide to bin-pack, sort, and Z-order compaction strategies for Apache Iceberg — when to use each, how to configure them, and how to automate strategy selection across hundreds of tables.

How to choose, evaluate, and evolve partitioning strategies for Apache Iceberg tables — decision frameworks for real workloads, partition lifecycle management, and when to change your strategy.

How STACKIT built a managed lakehouse offering on Kubernetes — custom operators, CRD-driven provisioning, multi-tenant Iceberg catalogs, and the engineering lessons from bringing a sovereign lakehouse service to market in Europe.

Running Iceberg at 10 tables is configuration. Running it at 10,000 is infrastructure. Production lessons on infrastructure evolution, Parquet tuning, Spark configuration, catalog scaling, enterprise security, and observability-driven optimization for production Iceberg deployments.

AI workloads running against Iceberg tables on S3 need more than fast queries — they need provably secure, least-privilege access to every byte they touch. This article walks through a zero-trust data architecture built on vended credentials, the Iceberg REST catalog, and Kubernetes-native orchestration — replacing static keys with short-lived, table-scoped tokens enforced at the storage layer.

AI agents fail in production because they are overwhelmed with data but starved for context. The bottleneck is not the model — it is the data stack. Apache Iceberg turns lakehouse storage into a live, versioned context layer that powers structured RAG, schema-aware agents, and governed reasoning grounded in truth.

How to migrate Delta Lake tables to Apache Iceberg without copying or rewriting data files. Covers zero-copy metadata conversion, the mapping between Delta transaction logs and Iceberg manifest trees, Iceberg V3 spec compatibility, practical tooling (XTable, UniForm, Iceberg Delta module), and the post-migration operational discipline — compaction, sort optimization, statistics — that determines whether converted tables actually perform.

Iceberg deliberately avoids embedding governance into its table format — access control, classification, and policy enforcement belong in the catalog and policy engine layers. This article lays out the three-layer model: table format for data portability, catalog control plane for enforcement, and pluggable policy engines for rules. How Polaris, OPA, and Ranger fit together in production multi-engine lakehouses.

Iceberg V3 brings row-level lineage, default column values, and deletion vectors — the features streaming pipelines need for governance without downtime. How V3 changes the streaming governance story on Flink, Kafka, and CDC sources.

How Apache projects have assembled a fully modular, vendor-neutral lakehouse stack — covering table formats (Iceberg, Hudi, Paimon), REST catalogs (Polaris, Gravitino), compute engines (Spark, Trino, Flink), real-time ingestion (Fluss), and why the operational gap demands an autonomous control plane.

Apache Iceberg does not ship with observability — data platform teams need table health, engine metrics, cost attribution, and lineage across Spark, Trino, and Flink. The seven pillars of lakehouse monitoring and how a control plane makes it operational.

Hot/cold data tiering on Apache Iceberg — StarRocks for sub-second dashboards, Iceberg for petabyte history, one SQL surface via federation. Ingestion, tier transitions, dedup, and keeping the cold tier fast.

LinkedIn runs Iceberg CDC on 10,000+ tables — billions of upserts daily, 2+ PB throughput. Equality vs position deletes, delete-file compaction, budgeted maintenance, and WAP branching lessons for any team running MERGE INTO at scale.

Build a streaming lakehouse on Apache Iceberg — unify Kafka/Flink ingestion and batch analytics without duplicating data. Production patterns, maintenance reality, and how to keep streaming Iceberg tables performant.

Star schema ETL and multi-table CDC need atomic commits across Iceberg tables — not just single-table ACID. How the REST Catalog transaction API, Polaris, Nessie, and Gravitino enable cross-table atomicity, and what teams run in production today.

When Iceberg metadata grows to hundreds of gigabytes, query planning — not Parquet reads — becomes the bottleneck. A practical guide for data platform teams on manifest rewriting, snapshot expiration, statistics, and metadata health at petabyte scale.

Apache Iceberg query planning is the coordinator-bound bottleneck before any parallel scan starts. This guide covers predicate pushdown, manifest list pruning, file-level data skipping, and what data platform teams do to keep planning fast as tables grow.

A comprehensive migration guide covering three source patterns — Hive/HMS tables, raw Parquet on S3, and Delta Lake — with three migration approaches (in-place, CTAS, shadow), post-migration operations, validation checklists, and common pitfalls. Includes production SQL, config examples, and the operational discipline teams underestimate after conversion.

Data quality and table health are different failure modes — one breaks business trust, the other breaks performance silently. A practical guide to the metrics, monitoring queries, classification frameworks, and automated remediation that keep Iceberg tables reliable in production.

Schema evolution is one of Iceberg's most powerful features — but misusing it in production causes silent downstream failures, broken statistics, and multi-engine inconsistencies. A practical guide to safe schema changes, column ID mechanics, partition evolution, branch-based testing, rollback strategies, and monitoring schema drift across the lakehouse.

A practical guide for migrating Apache Iceberg catalogs — from Hive Metastore to REST (Polaris, Gravitino), AWS Glue, Nessie, or Unity Catalog. Covers in-place metadata registration, dual-catalog access, validation, rollback strategies, and multi-catalog federation with LakeOps.

How production Iceberg lakehouses run Spark, Trino, Snowflake, Athena, Flink, and DuckDB on the same tables — covering engine decoupling, write isolation, conflict resolution, catalog coordination, read path optimization, query routing, cross-engine governance, and the control plane that ties it together.

Orphan files are invisible to Iceberg but fully billable by cloud storage. They accumulate silently from failed writes, crashed compaction, and concurrent conflicts — and on mature lakes they can account for 25–40% of storage spend. This guide covers how orphan files are created, how to detect them safely, the retention window that prevents table corruption, and how to automate cleanup at lake scale without listing millions of objects.

Every Iceberg commit creates a snapshot. Left unmanaged, snapshots pin storage, inflate metadata, and slow query planning. This guide covers what snapshots actually cost, retention strategies by workload type, the retain_last vs older_than tradeoffs, compliance via tags and branches, the cascade from snapshots to orphan files to manifest bloat, and how to set automated retention policies that match your operational reality.

Every concurrent write to an Apache Iceberg table risks a commit conflict. This guide covers how Iceberg's optimistic concurrency works, what triggers CommitFailedException, the common conflict scenarios in streaming and maintenance workloads, and the strategies — from partition isolation to branch-based writes — that eliminate conflicts in production.

A production-ready runbook for Iceberg incidents: queries suddenly slow, planning takes minutes, write conflicts spike, storage grows uncontrolled, compaction OOMs, time travel breaks, and delete files degrade reads. Each incident follows Symptom → Root Cause → Diagnosis → Fix → Prevention.

Taking Apache Iceberg from proof-of-concept to enterprise production requires decisions across ten operational dimensions — catalog architecture, table design, write path tuning, maintenance automation, observability, multi-engine coordination, security, disaster recovery, cost management, and on-call readiness. This checklist covers each one with concrete configurations, SQL examples, and the automation patterns that keep large-scale lakehouses healthy.

Apache Iceberg ships the maintenance primitives — compaction, snapshot expiration, orphan cleanup, and manifest rewriting — but none of them run themselves. This guide covers why each operation matters, the correct execution order, the limitations of scripts and cron jobs, and how to automate the full lifecycle with policies, observability, and a purpose-built control plane.

A practical guide to streaming data from Apache Kafka into Apache Iceberg tables — covering Kafka Connect, Apache Flink, Spark Structured Streaming, and CDC with Debezium. Includes configuration examples, schema management, partitioning strategies, production pitfalls, and how to keep streaming tables healthy at scale.

Apache Iceberg 1.11.0 lands V3 maturity with production-ready deletion vectors, a native Variant type for semi-structured data, server-side scan planning, built-in table encryption, and a pluggable File Format API that opens the door to next-generation storage formats.

AI agents are becoming primary consumers of Iceberg lakehouse data — querying tables iteratively, at high frequency, and without human review. This guide walks through the five components your infrastructure needs to support agentic workloads — MCP connectivity, guardrails, multi-engine routing, self-optimizing storage, and observability — and shows how LakeOps provides each one.

Netflix spent years building an intelligent lakehouse — Polaris for catalog management, Autotune for compaction, janitors for cleanup, and Metacat for observability. LakeOps lets every team build the same — and go beyond — in minutes. Here is what an intelligent lakehouse actually requires, and how LakeOps provides each component.

AWS Glue provides native Iceberg support for cataloging, ETL, and built-in table maintenance — but production lakehouses hit limitations fast. This guide covers Glue catalog configuration, ETL best practices, compaction tuning, common pitfalls, and how a dedicated control plane fills the operational gaps.

Databricks to Iceberg smooth migration opens a multi-engine lakehouse — not a platform exit. Databricks stays central for ML and Spark; Iceberg adds Trino, Snowflake, and open catalogs. Five tools: LakeOps, UC managed Iceberg, Delta UniForm, Spark, and Lakehouse Federation.

dbt transforms your data — but who maintains the Iceberg tables underneath? A practical guide to dbt adapters, incremental strategies, table properties, and the maintenance gap that every dbt + Iceberg team hits in production.

Flink streaming into Iceberg creates thousands of small files per hour. This guide covers checkpoint tuning, write distribution modes, Flink SQL patterns, and why external maintenance is essential for production streaming tables.

Delete files let Iceberg avoid rewriting data on every UPDATE or DELETE — but every unresolved delete file forces readers to reconcile at query time. A deep guide to position deletes, equality deletes, measuring overhead, and resolving accumulation before it tanks performance.

Partitioning determines how much data every query must scan. Apache Iceberg's hidden partitioning and partition evolution change the game — but choosing the wrong strategy still creates performance cliffs. A practical guide to transforms, sizing, evolution, and avoiding the small-files trap.

Puffin files store table-level statistics — NDV sketches and custom blobs — that query engines use for join ordering, split planning, and cost-based optimization. A practical guide to how they work, how to collect them, how they go stale, and how to keep them accurate at scale.

Iceberg tables degrade silently in production — small files multiply, snapshots accumulate, orphans waste storage, and manifests fragment. A comprehensive guide to the five maintenance operations, why sequencing matters, the metrics that reveal problems early, and how to automate the full lifecycle.

A practical guide to optimizing Apache Iceberg queries and table maintenance with Trino — covering scan planning, predicate pushdown, file pruning, Trino-side tuning, maintenance procedures, physical layout optimization, and how a dedicated control plane eliminates JVM overhead while adding cross-engine intelligence.

Apache Iceberg on AWS S3 is the standard architecture for open lakehouses. This guide covers how Iceberg's metadata hierarchy maps to S3 objects, the AWS services ecosystem (Glue, Athena, EMR, Redshift, S3 Tables), configuration best practices, performance optimization, table maintenance, and the operational components needed for production deployments.

AWS S3 bills for Iceberg lakehouses are inflated by small files, orphan data, retained snapshots, metadata overhead, and scan amplification. This guide quantifies each cost vector with S3 pricing mechanics and walks through five strategies — compaction, expiration, layout optimization, storage tiering, and engine routing — to cut storage and query spend.

A practical guide for senior data engineers expanding Snowflake into a multi-engine Iceberg lakehouse. Covers five production tools — LakeOps, managed Iceberg, Open Catalog sync, Spark, and AWS Glue — with migration patterns, operational trade-offs, and a phased rollout sequence.

State of Iceberg FinOps in 2026: where lakehouse spend leaks, what to measure, how autonomous management and optimization are replacing manual maintenance — and a practical survey of tools from cloud optimizers to control planes.

How to route queries across Trino, Spark, DuckDB, Snowflake, Athena, and Flink on shared Iceberg tables — covering the architecture of a SQL routing proxy, dialect translation, routing strategies, table-aware optimization, and the tooling that makes it work.

A technical comparison of the seven major Apache Iceberg catalogs — Hive Metastore, AWS Glue, Apache Polaris, Project Nessie, Databricks Unity Catalog, Apache Gravitino, and Lakekeeper — across protocol support, access control, multi-engine interoperability, credential vending, and production readiness.

Eight optimization layers for data platform engineers running BI, ad-hoc SQL, and aggregation pipelines on Apache Iceberg — from partition design and file sizing through compaction, routing, and continuous maintenance.

A deep technical guide to managing the metadata layer that makes Apache Iceberg fast — snapshots, manifests, metadata.json files, and Puffin statistics — covering expiration, consolidation, orphan cleanup, and the sequencing that prevents production incidents.

Iceberg lakehouses silently accumulate cost from small files, dead snapshots, orphan data, unoptimized layouts, and over-provisioned compute. Seven practical strategies — from deploying an autonomous control plane to leveraging partition evolution — that production data teams use to cut lakehouse spend by up to 80%.

Iceberg tables degrade silently — small files from streaming, unsorted data, fragmented manifests, accumulated delete files. Each one caps query speed regardless of engine. Six concrete optimization layers, how they interact, and how autonomous maintenance keeps every table at peak performance.

Data lakes, warehouses, and lakehouses are not interchangeable — each has hard limits the others cannot cover. A practical guide for platform leaders: where each architecture wins, where it fails, cost and governance trade-offs, and how to choose (or combine) them in 2026.

Compaction keeps Apache Iceberg lakehouses fast and lean — but every tool approaches it differently. A side-by-side look at nine production options: LakeOps, AWS Glue, Amazon S3 Tables, Snowflake, Google BigLake, Cloudera, Starburst, Dremio, and Databricks.

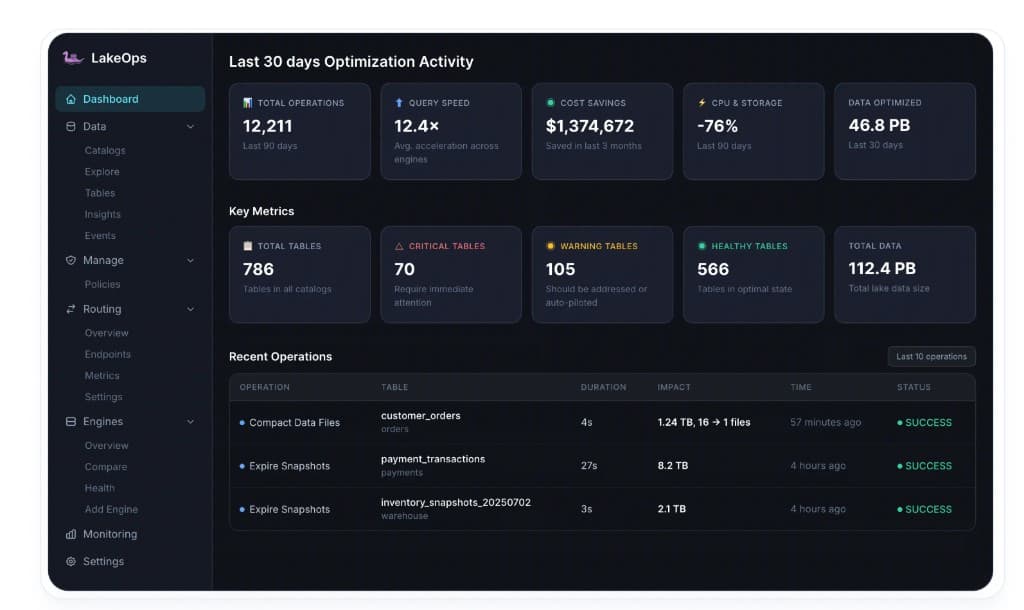
A practical walkthrough of optimizing an Apache Iceberg lakehouse end to end — from connecting catalogs and diagnosing table health through autonomous compaction, lifecycle management, and multi-engine routing to measurable cost and performance outcomes.

Every data lake starts with a promise of unlimited flexibility — and most end up as a swamp. Stale files, broken schemas, no observability, and engineers spending more time maintaining pipelines than analyzing data. Apache Iceberg fixed the reliability gap. A lakehouse control plane fixes everything else. A practical guide to the full transition — component by component.

Compaction is the most impactful operation in an Apache Iceberg lakehouse — and the hardest to get right at scale. File merging is the easy part. Knowing when to trigger it, what sort strategy to apply per table, how to avoid conflicting with other maintenance, and how to do it without spinning up expensive JVM clusters — that is the real problem. A breakdown of what modern compaction actually requires.

Apache Iceberg gives your lakehouse warehouse-grade reliability on object storage — but the format does not optimize itself. A practical guide to every operational pillar a production Iceberg lakehouse needs — from lake-wide observability and query-aware compaction to snapshot lifecycle, metadata health, and governance — and how LakeOps runs it all from a single control plane.

For a decade, Snowflake and Databricks defined enterprise data. Then the lakehouse emerged — open formats on open storage. What was missing was the operational layer to make it work at scale. An autonomous control plane turns a lakehouse into a managed open data platform — without the lock-in.

Your Iceberg lake is overcharging you from four directions at once — storage bloat, query compute waste, compaction overhead, and engineering time. This post breaks down exactly where each dollar goes and how autonomous table management eliminates the waste without touching your pipelines.

Iceberg tables degrade silently — small files pile up, snapshots bloat metadata, and query latency creeps higher. A breakdown of the nine components every production data lake needs to stay healthy — starting with observability and telemetry collection, through compaction, snapshot management, and lake-wide policies, to multi-engine routing and agentic AI enablement.

QueryFlux is a universal SQL proxy and multi-engine query router in Rust—one access layer in front of Trino, DuckDB, StarRocks, and Athena with routing, dialect translation, and observability.

How we compacted 4.5 TB across 10 real production tables, achieved up to 99.8% file reduction, and made Apache Spark OOM on a job we finished in 11 minutes.

How we built a high-performance, distributed compaction engine for Apache Iceberg using Rust and DataFusion—architecture, design choices, and lessons learned.
Apache Iceberg delivers speed, but without a control plane snapshots pile up, costs surge, query take more time — starting with expiration.

Unlocking performance vs. optimizing storage — choosing the right compaction strategy for your data lake.

A detailed comparison between Delta Lake and Apache Iceberg, exploring their architectures, performance characteristics, and ideal use cases to help you make the right choice.

Learn how to implement efficient incremental processing with Apache Iceberg and Spark, including best practices for data lake optimization and performance tuning.