Managed Iceberg in 2026: Autonomous Data Lake
Iceberg tables degrade silently — small files pile up, snapshots bloat metadata, and query latency creeps higher. A breakdown of the nine components every production data lake needs to stay healthy.
Guides and insights from the LakeOps team on Apache Iceberg,lakehouse architecture, and production operations.

Iceberg tables degrade silently — small files pile up, snapshots bloat metadata, and query latency creeps higher. A breakdown of the nine components every production data lake needs to stay healthy.

Netflix spent years building an intelligent lakehouse — Polaris, Autotune, janitors, and Metacat. LakeOps lets every team build the same — and go beyond — in minutes.

A data lakehouse control plane is the automated operational intelligence layer on top of your lakehouse infrastructure — providing full observability, governance, and control while continuously maintaining and optimizing every Iceberg table and query engine for performance and cost, without vendor lock-in.

Google engineered a multi-layered Iceberg lakehouse — autonomous storage optimization, vectorized native execution, catalog federation, and credential vending. Learn their 6-layer optimization framework and how to build the same architecture with an open, engine-neutral control plane.

How a data lakehouse works in production — the four architectural layers, Iceberg's metadata tree, data flow patterns, why tables degrade under real workloads, and the closed-loop control plane that keeps the system performing at scale.

How to route queries across Trino, Spark, DuckDB, Snowflake, Athena, and Flink on shared Iceberg tables — covering the architecture of a SQL routing proxy, dialect translation, routing strategies, table-aware optimization, and the tooling that makes it work.

Apache Iceberg 1.12.0 adds Hilbert-curve clustering, a Flink task that converts equality deletes into deletion vectors, V4 manifest readers with relative paths, and vectorized variant reads — while removing Spark 3.4, Flink 2.0, and position deletes carrying row data. Here is what changed and what it means for your tables.

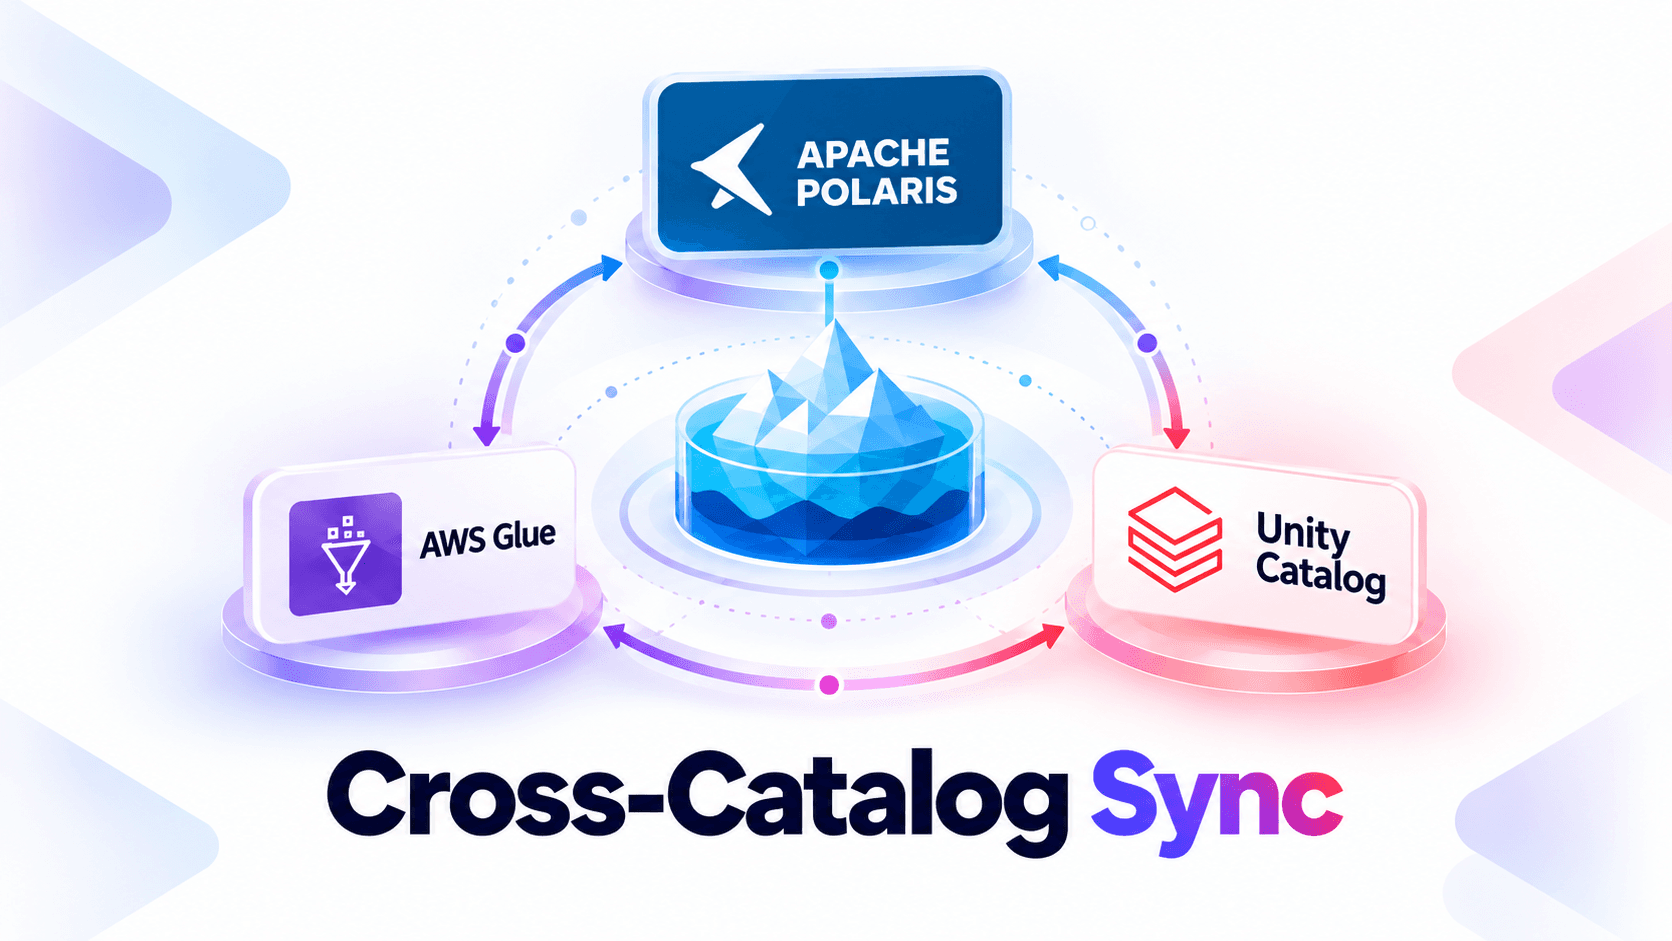
Three Iceberg catalogs, one lake, and no single operational view. Why bidirectional catalog sync is a correctness bug, how federation actually works across Polaris, Glue, and Unity Catalog, and how to run one operating model over catalogs that will never merge.

A practical guide to building a data lakehouse: object storage, Apache Iceberg, the catalog, the engine fleet, and the control plane that keeps every table fast and cheap.

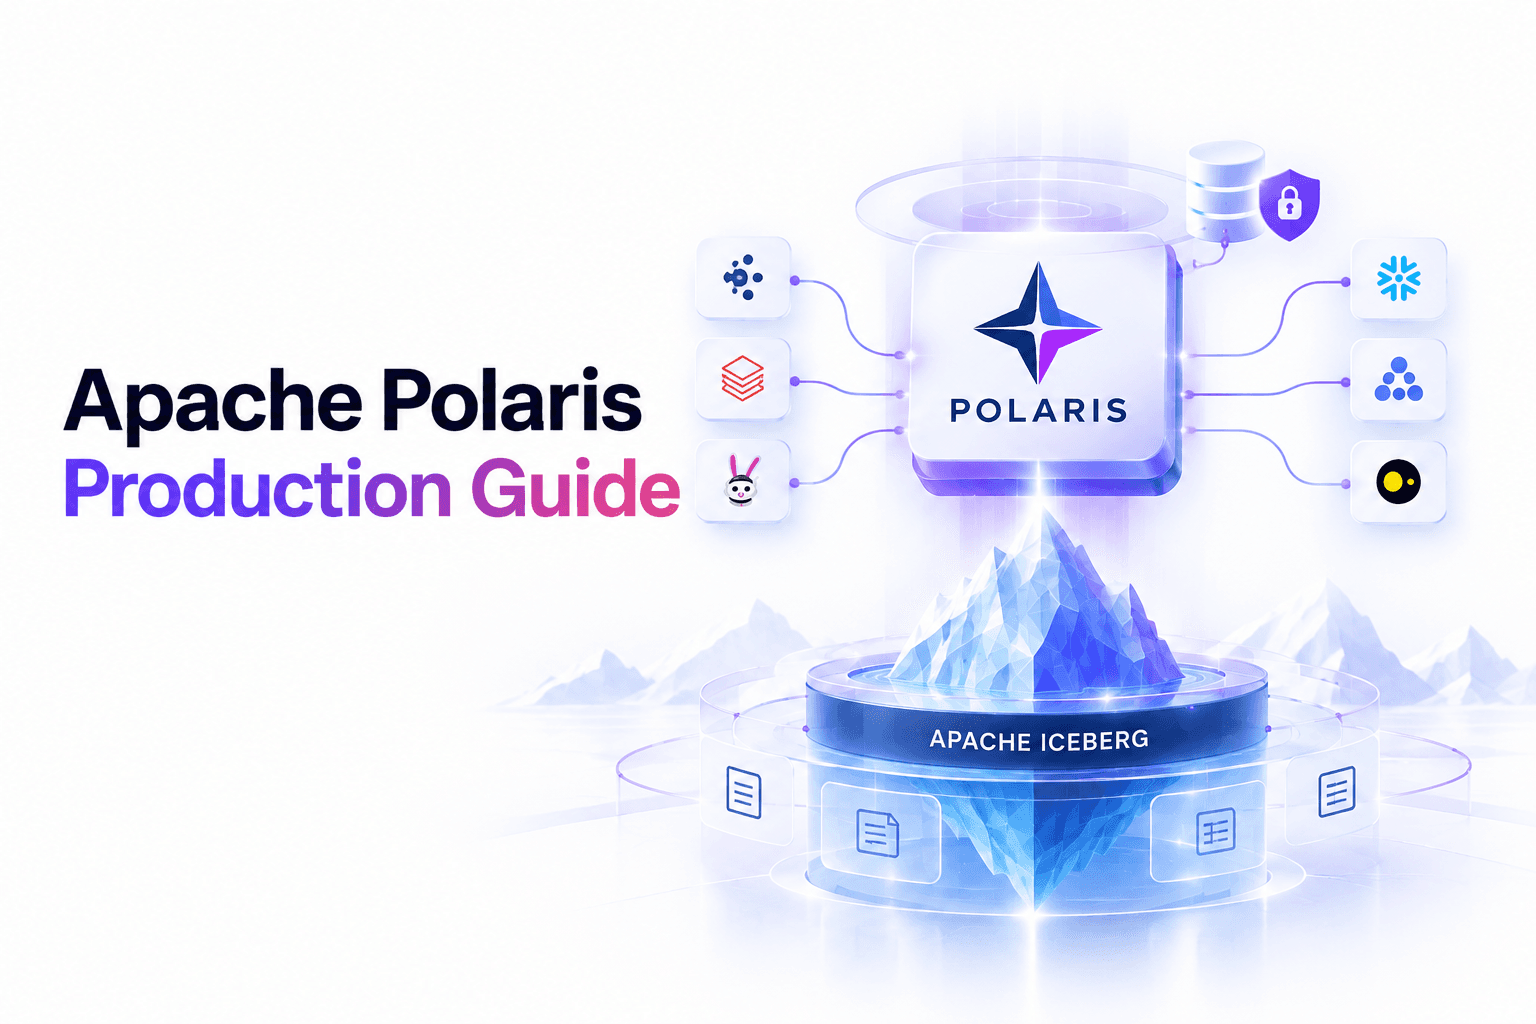
Apache Polaris is the open-source reference implementation of the Iceberg REST Catalog specification. This guide covers what Polaris actually does, how it fits into a production lakehouse, and what it takes to deploy, secure, and operate it — from persistence and realm bootstrap through credential vending, multi-engine access, RBAC, federation, and the operational concerns the quickstart does not mention.

AI agents are eliminating the BI bottleneck — translating natural language to SQL in seconds, routing queries to optimal engines, and producing analyst-grade insights autonomously. Learn how to build a production analytics system on Iceberg with multi-engine routing, guardrails, and self-optimizing storage.

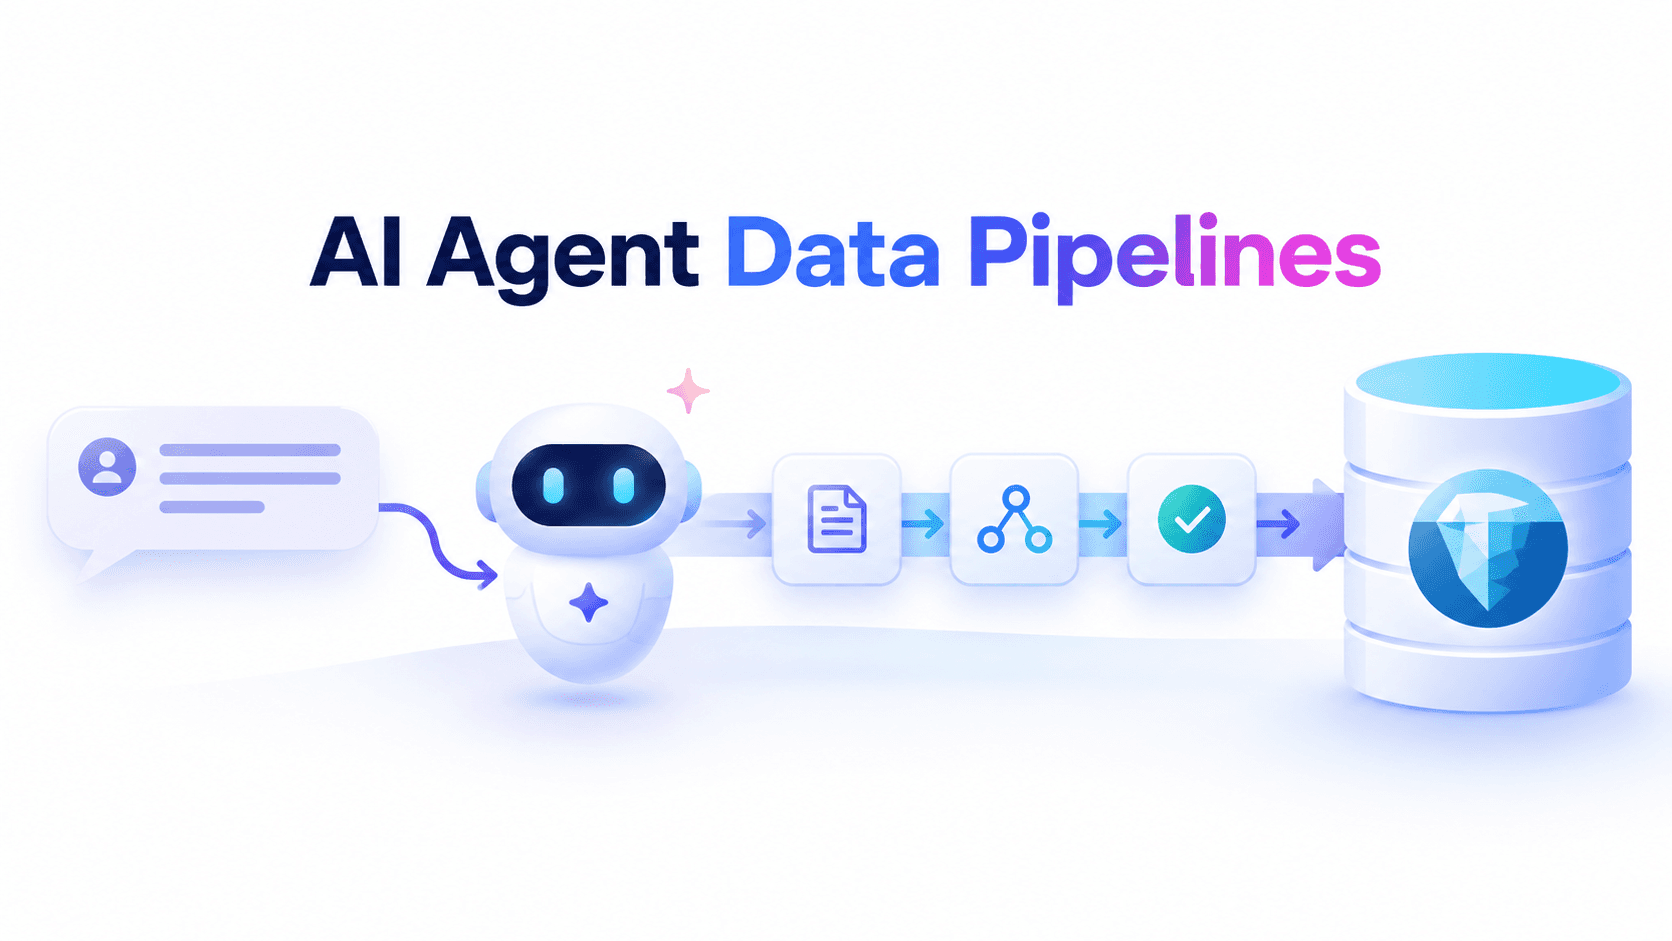
AI agents can now build data pipelines from natural language — discovering schemas via MCP, generating Iceberg-native SQL, routing each stage to the optimal engine, and validating results in a feedback loop. Here's the architecture that makes it work.