Back to all articles

Data Platforms articles

Architecture, strategy, and tooling for modern data platforms — from lakehouse design to multi-engine orchestration.

72 articles

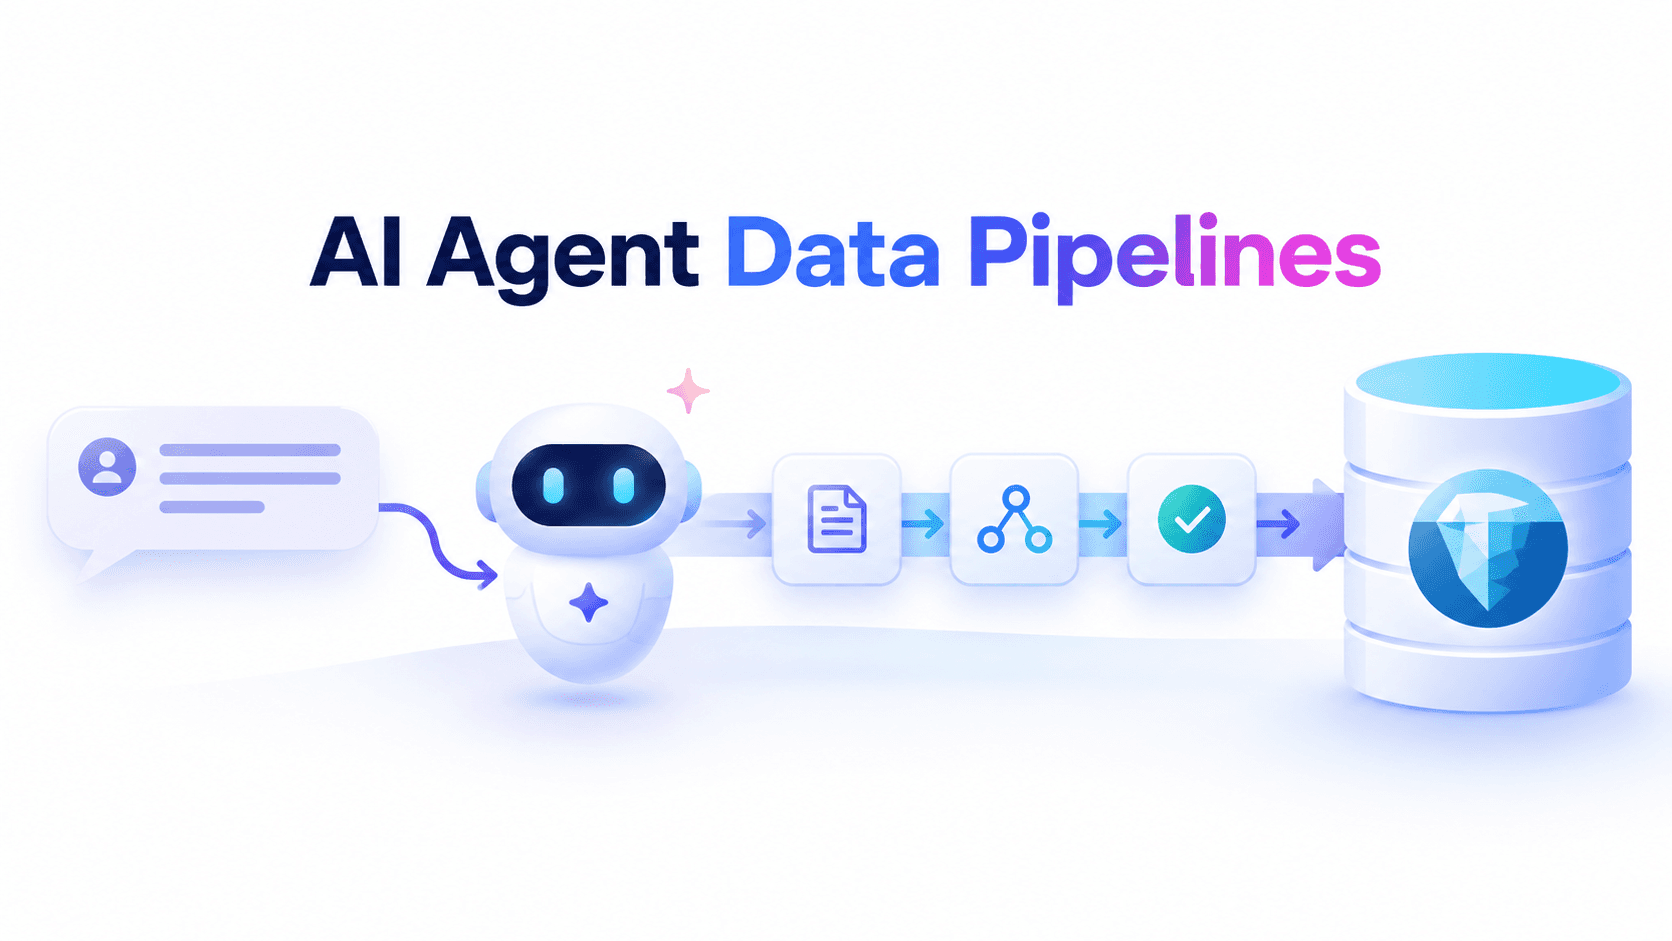
Building AI Agent Data Pipelines into Apache Iceberg
AIApache IcebergLakeOps

AI Agent Data Pipelines for Apache Iceberg: A Guide

AI agents can now build data pipelines from natural language — discovering schemas via MCP, generating Iceberg-native SQL, routing each stage to the optimal engine, and validating results in a feedback loop. Here's the architecture that makes it work.

Rob M
Rob M
17 min read
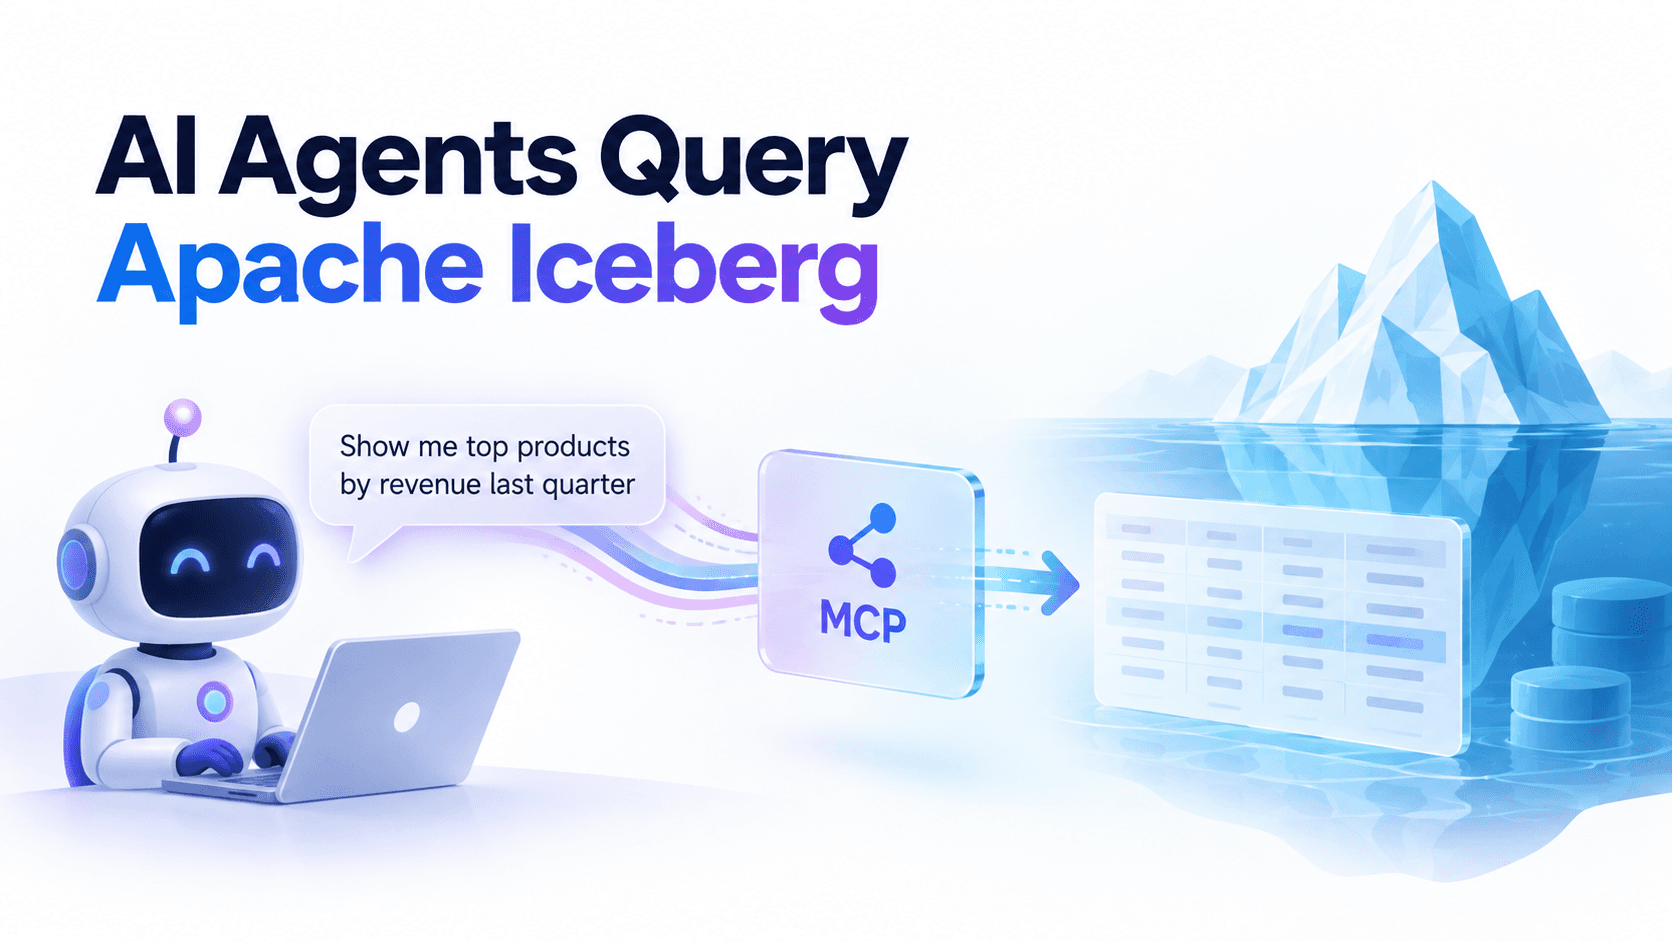
How AI Agents Query Apache Iceberg Data Using MCP and Natural Language
AIApache IcebergLakeOps

How AI Agents Query Apache Iceberg Data with MCP

A practical guide to how AI agents query Apache Iceberg tables using MCP — covering schema discovery, SQL generation, guardrails, multi-engine routing, and the control plane that ties it all together.

Rob M
Rob M
20 min read
How to Give AI Agents Safe Access to Apache Iceberg Data in Production
AIApache IcebergLakeOps

Safe AI Agent Access to Apache Iceberg in Production

AI agents querying production Iceberg tables can scan petabytes, leak PII, or drop tables — all without human review. This guide covers the guardrails, governance policies, and control plane architecture needed to give agents safe, governed access.

Chris P
Chris P
22 min read
Apache Iceberg for AI Agents: How to Make Your Lakehouse Data AI-Ready
AIApache IcebergLakeOps

Apache Iceberg for AI Agents: Make Your Lakehouse AI-Ready

The definitive guide to making your Apache Iceberg lakehouse AI-ready across six dimensions: discoverable, queryable, governed, observable, maintainable, and connected. Includes a practical readiness checklist and scoring framework.

David W
David W
30 min read
How to Connect AI Agents to Your Apache Iceberg Lakehouse with MCP
AIApache IcebergLakeOps

Connect AI Agents to Apache Iceberg with MCP

A step-by-step guide to connecting AI agents to your Apache Iceberg lakehouse using MCP and the LakeOps control plane — from API key setup to 27 auto-discovered tools for discovery, analysis, guardrails, and governance.

David W
David W
19 min read
Self-Healing Data Pipelines with AI Agents and Apache Iceberg
AIApache IcebergLakeOps

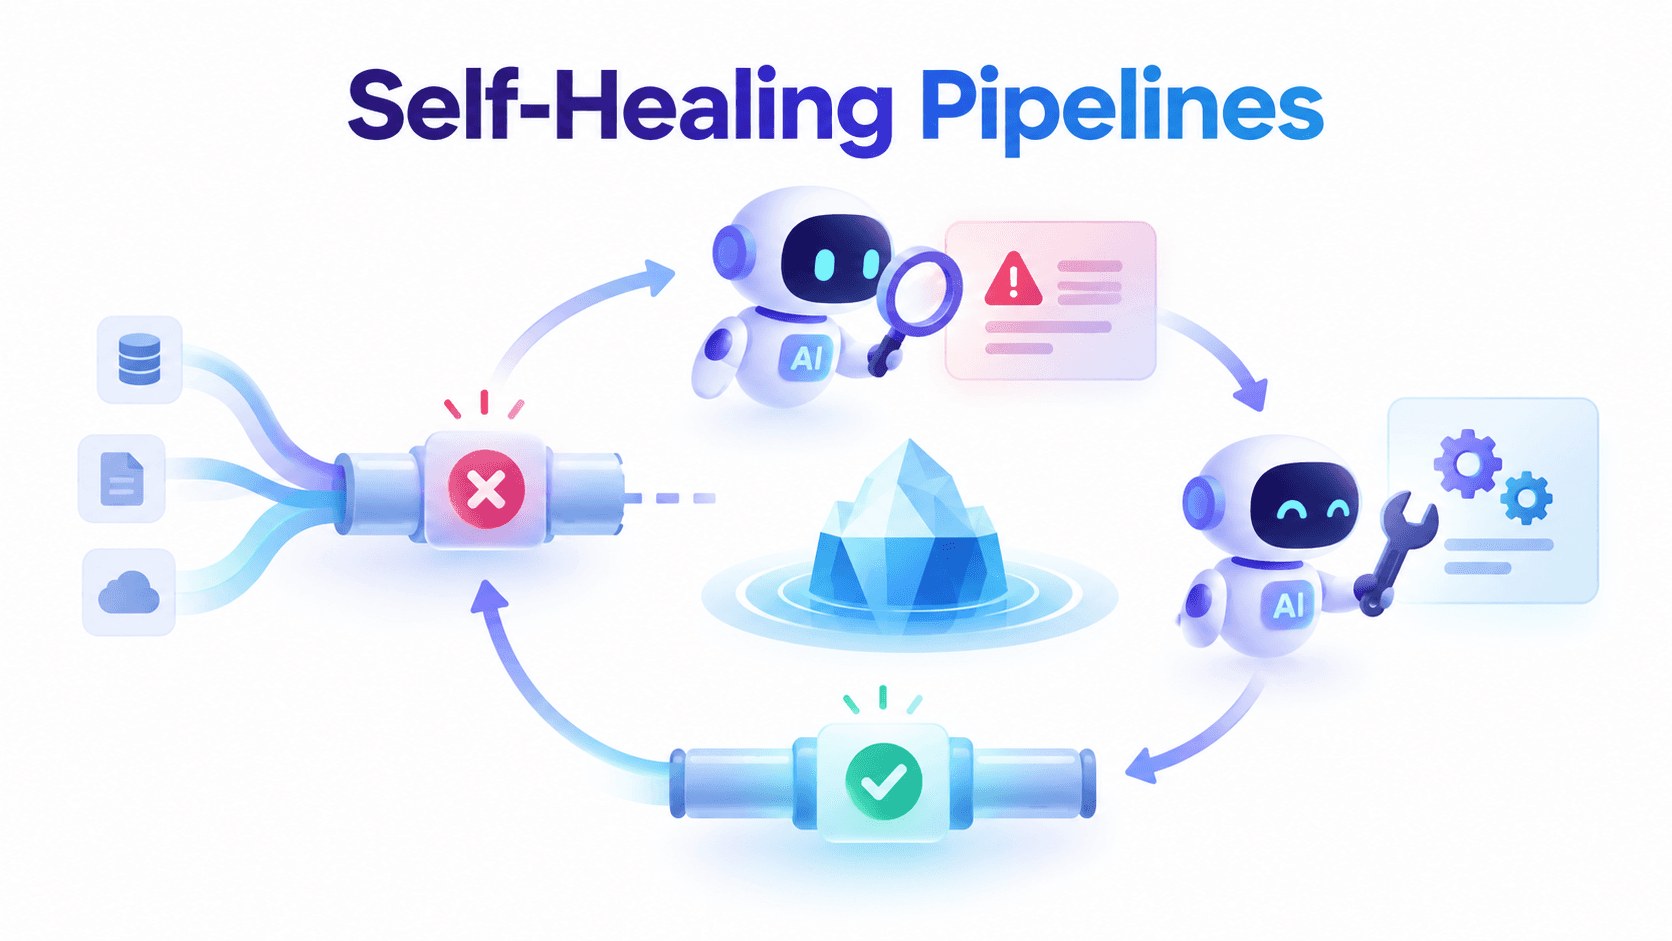
Self-Healing Data Pipelines with AI Agents on Iceberg

Data pipelines break constantly — schema drift, small files, snapshot bloat, partition skew. Self-healing pipelines use AI agents and Iceberg's metadata-rich format to detect, diagnose, fix, and verify issues autonomously before anyone wakes up at 3 AM.

David W
David W
23 min read
The Future Isn't One Engine — Spark, Trino, DuckDB, Snowflake, Flink, and StarRocks connected through an intelligent control plane above an Apache Iceberg lakehouse
Data PlatformsApache IcebergLakehouse

The Future Isn't One Engine. It's a Control Plane.

The future of data platforms isn't one engine. It's specialized engines on shared data, and a control plane that decides where each workload runs and how the tables stay fast.

Amit Gilad
Amit Gilad
10 min read
Apache Iceberg Lakehouse Architecture — five-layer stack from object storage through control plane with catalogs, engines, and autonomous optimization.
Data PlatformsApache IcebergLakehouse Architecture

Apache Iceberg Lakehouse Architecture: A Practical Guide

A practitioner's guide to Apache Iceberg lakehouse architecture — the five layers from object storage to control plane, design decisions at each layer, migration paths, security architecture, and how to build a production lakehouse that stays healthy at scale.

David W
David W
40 min read
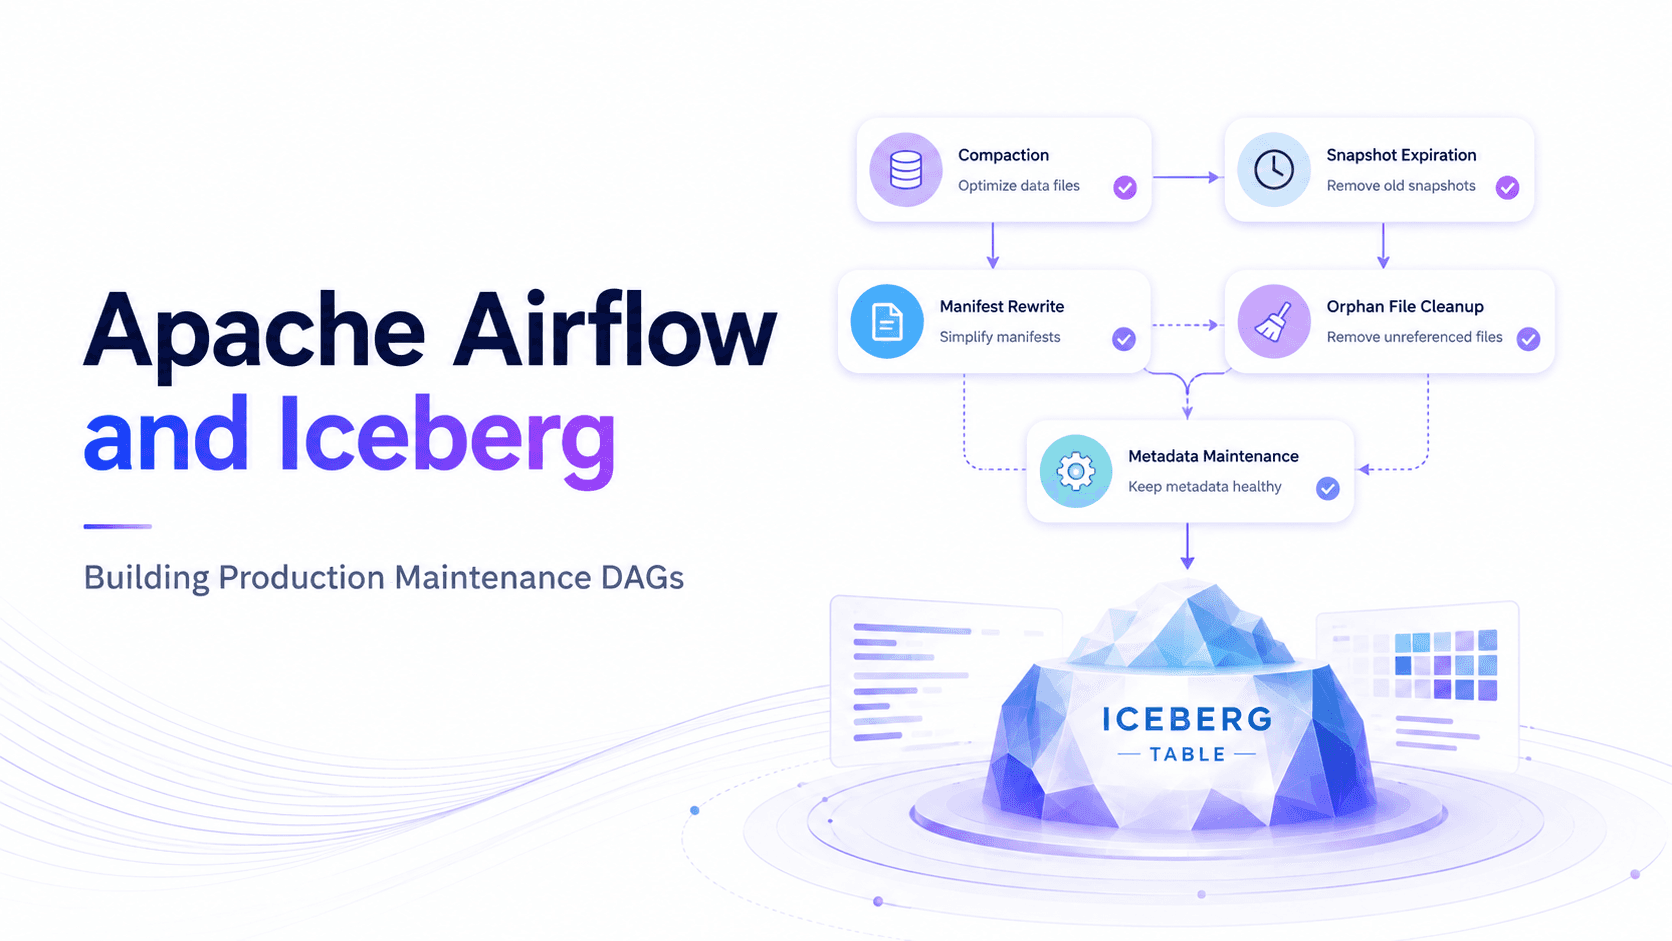
Data Lakehouse Maintenance with Apache Airflow — crystalline lakehouse on a floating island with the Airflow logo and Iceberg emblem
Data PlatformsApache AirflowData Lakehouse

Data Lakehouse Maintenance with Airflow: Why It Breaks

Most data lakehouse teams start maintaining Iceberg tables with Airflow DAGs and Spark SQL procedures. This guide covers the five structural pitfalls that emerge at scale — fixed schedules, per-table DAGs, JVM overhead, missing coordination, and blind-spot observability — and the autonomous control plane architecture that replaces them.

Jonathan Saring
Jonathan Saring
17 min read
Data Lakehouse with Apache Iceberg — layered architecture with control plane connecting catalogs, query engines, and object storage over Iceberg tables.
Data PlatformsData LakehouseApache Iceberg

Data Lakehouse with Apache Iceberg: A Guide

How a data lakehouse works in production — the four architectural layers, Iceberg's metadata tree, data flow patterns, why tables degrade under real workloads, and the closed-loop control plane that keeps the system performing at scale.

Jonathan Saring
Jonathan Saring
29 min read
Apache Iceberg Performance Optimizations — Nessie mascot beside a geometric iceberg with the Iceberg logo, illustrating lakehouse performance tuning from queries to tables.
Data PlatformsApache IcebergData Lakehouse

Apache Iceberg Performance Optimization: Queries to Tables

How Apache Iceberg performance actually works — the query execution pipeline, the five surfaces that degrade every production table, and the intelligent control plane that keeps file layout, sort order, metadata, and engine routing optimized continuously.

Jonathan Saring
Jonathan Saring
20 min read
Modern lakehouse architecture with LakeOps control plane — autonomous management and optimization connected to Iceberg catalogs, query engines, and object storage.
Data PlatformsData LakehouseApache Iceberg

What Is a Data Lakehouse Control Plane?

A data lakehouse control plane is the automated operational intelligence layer on top of your lakehouse infrastructure — providing full observability, governance, and control while continuously maintaining and optimizing every Iceberg table and query engine for performance and cost, without vendor lock-in.

Jonathan Saring
Jonathan Saring
13 min read
Open Data Lakehouse — Build like Google. Multi-layered Iceberg architecture with BigQuery, Spark, and open engines connected through an intelligent control plane.
Apache IcebergData LakehouseLakeOps

Open Data Lakehouse: Build Like Google

Google engineered a multi-layered Iceberg lakehouse — autonomous storage optimization, vectorized native execution, catalog federation, and credential vending. Learn their 6-layer optimization framework and how to build the same architecture with an open, engine-neutral control plane.

Jonathan Saring
Jonathan Saring
24 min read
DuckDB and Apache Iceberg — query, write, and optimize lakehouse tables without a Spark cluster
Apache IcebergLakeOpsCompaction

DuckDB for Apache Iceberg

Query and write Apache Iceberg tables with DuckDB — no cluster required. Catalog setup, MERGE INTO, time travel, table layout, and when to route to DuckDB vs Spark or Trino.

Rob M
Rob M
19 min read
AI Lakehouse — neural network brain connected to an iceberg data structure representing the evolution from data lake to AI-ready lakehouse
AIData LakehouseApache Iceberg

AI Lakehouse: The Complete Guide to Self-Managing Data Lakes

The AI lakehouse is what happens when your data lake stops being passive storage and starts managing itself. Autonomous maintenance, query-aware compaction, multi-engine routing, continuous observability, and an agent interface layer — all working together so the lake stays healthy, fast, and ready for both human analysts and AI agents.

David W
David W
19 min read
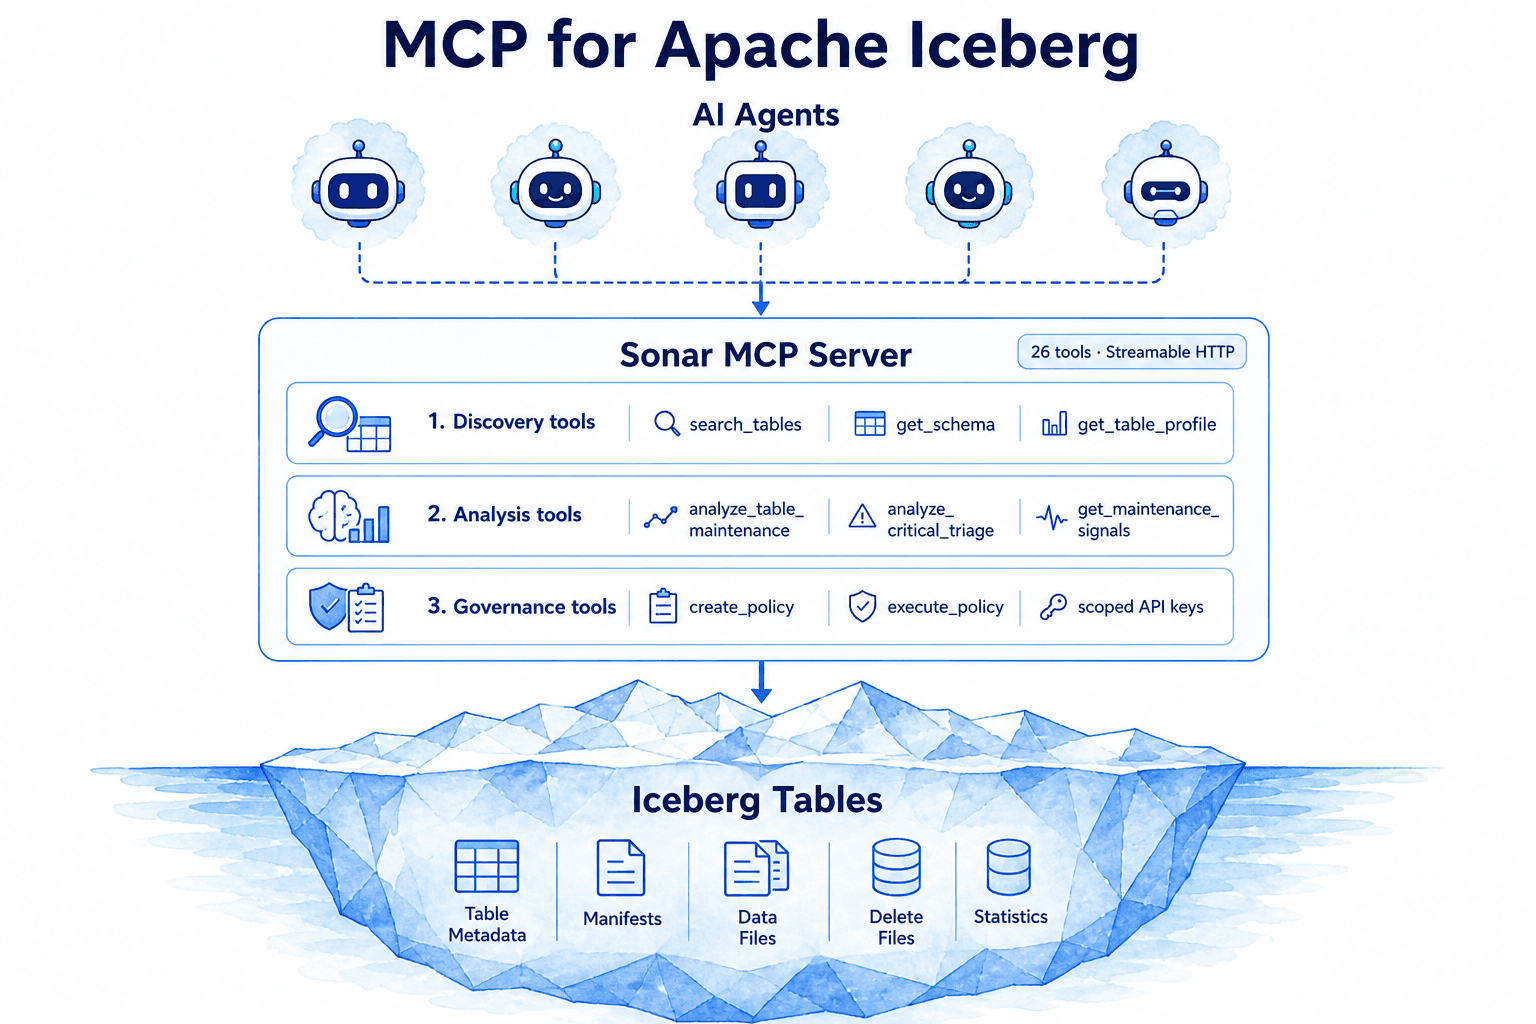
MCP for Apache Iceberg — AI agents connect through the LakeOps MCP server (discovery, analysis, and governance tools) to Iceberg table metadata
AIApache IcebergLakeOps

MCP for Apache Iceberg: How AI Agents Actually Operate a Data Lake

Your Iceberg tables are degrading right now — small files accumulating, snapshots pinning storage, manifests fragmenting — and the fix requires operational knowledge no LLM has in its weights. MCP bridges that gap. This post shows how purpose-built MCP tools turn AI agents from chat assistants into operational participants that discover, diagnose, and govern Iceberg tables with the same structured signals your best platform engineer uses.

Amit Gilad
Amit Gilad
23 min read
Iceberg Compaction Strategies — How to Choose: Bin-Pack, Sort, and Z-Order illustrated with before and after file layouts
CompactionApache IcebergLakeOps

Iceberg Lake Compaction Strategies: A Practical Guide

A deep guide to bin-pack, sort, and Z-order compaction strategies for Apache Iceberg — when to use each, how to configure them, and how to automate strategy selection across hundreds of tables.

Rob M
Rob M
17 min read
Iceberg Table Partitioning Strategies — A Practical Guide showing partition transforms splitting data into time, region, and category folders
PartitioningApache IcebergLakeOps

Iceberg Table Partitioning Strategies: A Practical Guide

How to choose, evaluate, and evolve partitioning strategies for Apache Iceberg tables — decision frameworks for real workloads, partition lifecycle management, and when to change your strategy.

Chris P
Chris P
16 min read
Building a lakehouse as a service on Kubernetes with Apache Iceberg
Data PlatformsApache IcebergKubernetes

Building a Lakehouse as a Service on Kubernetes with Apache Iceberg

How STACKIT built a managed lakehouse offering on Kubernetes — custom operators, CRD-driven provisioning, multi-tenant Iceberg catalogs, and the engineering lessons from bringing a sovereign lakehouse service to market in Europe.

Chris P
Chris P
28 min read
Apache Iceberg at scale — infrastructure, performance, and enterprise lessons
Apache IcebergData PlatformsLakeOps

Apache Iceberg at Scale: Infrastructure, Performance, and Enterprise Lessons

Running Iceberg at 10 tables is configuration. Running it at 10,000 is infrastructure. Production lessons on infrastructure evolution, Parquet tuning, Spark configuration, catalog scaling, enterprise security, and observability-driven optimization for production Iceberg deployments.

David W
David W
33 min read
Zero-trust data architecture for AI workloads on Apache Iceberg and S3
Data PlatformsApache IcebergData Governance

Zero-Trust Data Architecture for AI Workloads on Apache Iceberg and S3

AI workloads running against Iceberg tables on S3 need more than fast queries — they need provably secure, least-privilege access to every byte they touch. This article walks through a zero-trust data architecture built on vended credentials, the Iceberg REST catalog, and Kubernetes-native orchestration — replacing static keys with short-lived, table-scoped tokens enforced at the storage layer.

Rob M
Rob M
32 min read
Iceberg for AI agents — turning lakehouse data into AI-ready context with structured RAG
Data PlatformsApache IcebergAI

Iceberg for AI Agents: Turning Lakehouse Data Into AI-Ready Context

AI agents fail in production because they are overwhelmed with data but starved for context. The bottleneck is not the model — it is the data stack. Apache Iceberg turns lakehouse storage into a live, versioned context layer that powers structured RAG, schema-aware agents, and governed reasoning grounded in truth.

Jonathan Saring
Jonathan Saring
26 min read
Delta Lake to Apache Iceberg zero-copy migration — metadata conversion without moving data
Apache IcebergDelta LakeLakeOps

Delta Lake to Apache Iceberg: Zero-Copy Migration Without Moving Data

How to migrate Delta Lake tables to Apache Iceberg without copying or rewriting data files. Covers zero-copy metadata conversion, the mapping between Delta transaction logs and Iceberg manifest trees, Iceberg V3 spec compatibility, practical tooling (XTable, UniForm, Iceberg Delta module), and the post-migration operational discipline — compaction, sort optimization, statistics — that determines whether converted tables actually perform.

David W
David W
30 min read
Apache Iceberg lakehouse governance — separation of concerns with Polaris and policy engines
Apache IcebergData GovernanceLakehouse

Apache Iceberg Lakehouse Governance: Separation of Concerns with Polaris and Policy Engines

Iceberg deliberately avoids embedding governance into its table format — access control, classification, and policy enforcement belong in the catalog and policy engine layers. This article lays out the three-layer model: table format for data portability, catalog control plane for enforcement, and pluggable policy engines for rules. How Polaris, OPA, and Ranger fit together in production multi-engine lakehouses.

Chris P
Chris P
26 min read
Apache Iceberg V3 for streaming — row-level lineage, schema evolution, and governance
Apache IcebergStreamingData Governance

Apache Iceberg V3 for Streaming: Row-Level Lineage, Schema Evolution, and Governance

Iceberg V3 brings row-level lineage, default column values, and deletion vectors — the features streaming pipelines need for governance without downtime. How V3 changes the streaming governance story on Flink, Kafka, and CDC sources.

Rob M
Rob M
27 min read
The rise of the open Apache lakehouse — modular vendor-neutral architecture with Iceberg, Polaris, and Fluss
Data PlatformsApache IcebergData Lakehouse

The Rise of the Open Apache Lakehouse: Modular Architecture for Vendor-Neutral Data Platforms

How Apache projects have assembled a fully modular, vendor-neutral lakehouse stack — covering table formats (Iceberg, Hudi, Paimon), REST catalogs (Polaris, Gravitino), compute engines (Spark, Trino, Flink), real-time ingestion (Fluss), and why the operational gap demands an autonomous control plane.

Jonathan Saring
Jonathan Saring
28 min read
Apache Iceberg lakehouse observability — monitoring what matters in production
Apache IcebergObservabilityLakeOps

Iceberg Lakehouse Observability: Monitor Table Health, Costs, and Query Performance

Apache Iceberg does not ship with observability — data platform teams need table health, engine metrics, cost attribution, and lineage across Spark, Trino, and Flink. The seven pillars of lakehouse monitoring and how a control plane makes it operational.

Jonathan Saring
Jonathan Saring
29 min read
Hot and cold data tiering on Apache Iceberg with StarRocks — real-time analytics architecture
Data PlatformsApache IcebergAnalytics

Iceberg Hot and Cold Data Tiering: StarRocks + Iceberg for Real-Time Analytics

Hot/cold data tiering on Apache Iceberg — StarRocks for sub-second dashboards, Iceberg for petabyte history, one SQL surface via federation. Ingestion, tier transitions, dedup, and keeping the cold tier fast.

Chris P
Chris P
34 min read
How LinkedIn scales Apache Iceberg CDC ingestion to billions of upserts per day
Data PlatformsApache IcebergStreaming

Iceberg CDC at Scale: How LinkedIn Ingests Billions of Upserts Per Day

LinkedIn runs Iceberg CDC on 10,000+ tables — billions of upserts daily, 2+ PB throughput. Equality vs position deletes, delete-file compaction, budgeted maintenance, and WAP branching lessons for any team running MERGE INTO at scale.

Rob M
Rob M
26 min read
Streaming lakehouse on Apache Iceberg — multi-engine data ingestion into Iceberg tables
Data PlatformsApache IcebergStreaming

Streaming Lakehouse on Apache Iceberg: Kafka, Flink, and Real-Time Pipelines Without Duplication

Build a streaming lakehouse on Apache Iceberg — unify Kafka/Flink ingestion and batch analytics without duplicating data. Production patterns, maintenance reality, and how to keep streaming Iceberg tables performant.

Jonathan Saring
Jonathan Saring
27 min read
Multi-table transactions in Apache Iceberg — cross-table atomicity for the open lakehouse
Apache IcebergLakeOpsData Governance

Iceberg Multi-Table Transactions: Cross-Table Atomicity for Production Lakehouses

Star schema ETL and multi-table CDC need atomic commits across Iceberg tables — not just single-table ACID. How the REST Catalog transaction API, Polaris, Nessie, and Gravitino enable cross-table atomicity, and what teams run in production today.

Chris P
Chris P
16 min read
Apache Iceberg metadata at petabyte scale — manifests, statistics, and planning performance
Apache IcebergLakeOpsCompaction

Iceberg Metadata at Scale: Keep Query Planning Fast on Petabyte Tables

When Iceberg metadata grows to hundreds of gigabytes, query planning — not Parquet reads — becomes the bottleneck. A practical guide for data platform teams on manifest rewriting, snapshot expiration, statistics, and metadata health at petabyte scale.

David W
David W
30 min read
Apache Iceberg query planning internals — predicate pushdown, manifest filtering, and data skipping
Apache IcebergAnalyticsLakeOps

Apache Iceberg Query Planning Explained: Predicate Pushdown, Manifest Filtering, and Data Skipping

Apache Iceberg query planning is the coordinator-bound bottleneck before any parallel scan starts. This guide covers predicate pushdown, manifest list pruning, file-level data skipping, and what data platform teams do to keep planning fast as tables grow.

Rob M
Rob M
25 min read
Apache Iceberg Migration Strategy — from Hive, Parquet, or Delta to production Iceberg
Data PlatformsApache IcebergDelta Lake

Apache Iceberg Migration Strategy: From Hive, Parquet, or Delta to Production Iceberg

A comprehensive migration guide covering three source patterns — Hive/HMS tables, raw Parquet on S3, and Delta Lake — with three migration approaches (in-place, CTAS, shadow), post-migration operations, validation checklists, and common pitfalls. Includes production SQL, config examples, and the operational discipline teams underestimate after conversion.

Jonathan Saring
Jonathan Saring
33 min read
Apache Iceberg Data Quality and Table Health — where reliability actually breaks, healthy vs unhealthy comparison
Apache IcebergObservabilityLakeOps

Apache Iceberg Data Quality and Table Health: Where Reliability Actually Breaks

Data quality and table health are different failure modes — one breaks business trust, the other breaks performance silently. A practical guide to the metrics, monitoring queries, classification frameworks, and automated remediation that keep Iceberg tables reliable in production.

David W
David W
26 min read
Apache Iceberg Schema Evolution in Production — best practices and pitfalls across the lakehouse architecture
Apache IcebergData GovernanceLakeOps

Apache Iceberg Schema Evolution in Production: Best Practices and Pitfalls

Schema evolution is one of Iceberg's most powerful features — but misusing it in production causes silent downstream failures, broken statistics, and multi-engine inconsistencies. A practical guide to safe schema changes, column ID mechanics, partition evolution, branch-based testing, rollback strategies, and monitoring schema drift across the lakehouse.

Rob M
Rob M
28 min read
Apache Iceberg Catalog Migration — Hive Metastore to REST, Polaris, Glue, or Nessie
Apache IcebergData PlatformsLakeOps

Apache Iceberg Catalog Migration: Hive Metastore to REST, Polaris, Glue, or Nessie

A practical guide for migrating Apache Iceberg catalogs — from Hive Metastore to REST (Polaris, Gravitino), AWS Glue, Nessie, or Unity Catalog. Covers in-place metadata registration, dual-catalog access, validation, rollback strategies, and multi-catalog federation with LakeOps.

Chris P
Chris P
30 min read
Apache Iceberg Multi-Engine Architecture — Spark, Trino, Snowflake, and Athena on the same Iceberg tables
Data PlatformsData LakehouseApache Iceberg

Apache Iceberg Multi-Engine Architecture: Spark, Trino, Snowflake, Athena on the Same Tables

How production Iceberg lakehouses run Spark, Trino, Snowflake, Athena, Flink, and DuckDB on the same tables — covering engine decoupling, write isolation, conflict resolution, catalog coordination, read path optimization, query routing, cross-engine governance, and the control plane that ties it together.

Jonathan Saring
Jonathan Saring
27 min read
Apache Iceberg Operational Runbook — incidents, symptoms, and fixes with detect, diagnose, resolve, and verify workflow
Apache IcebergObservabilityLakeOps

Apache Iceberg Operational Runbook: Incidents, Symptoms, and Fixes

A production-ready runbook for Iceberg incidents: queries suddenly slow, planning takes minutes, write conflicts spike, storage grows uncontrolled, compaction OOMs, time travel breaks, and delete files degrade reads. Each incident follows Symptom → Root Cause → Diagnosis → Fix → Prevention.

David W
David W
24 min read
Apache Iceberg Production Readiness Checklist for Enterprise Data Lakes — security, storage, operations, and governance
Apache IcebergData LakehouseLakeOps

Apache Iceberg Production Readiness Checklist for Enterprise Data Lakes

Taking Apache Iceberg from proof-of-concept to enterprise production requires decisions across ten operational dimensions — catalog architecture, table design, write path tuning, maintenance automation, observability, multi-engine coordination, security, disaster recovery, cost management, and on-call readiness. This checklist covers each one with concrete configurations, SQL examples, and the automation patterns that keep large-scale lakehouses healthy.

Rob M
Rob M
25 min read
Automating Apache Iceberg Table Maintenance — compaction, snapshot expiration, orphan cleanup, manifest rewrite, and table health orbiting an Iceberg table.
Apache IcebergCompactionLakeOps

Automating Apache Iceberg Table Maintenance

Apache Iceberg ships the maintenance primitives — compaction, snapshot expiration, orphan cleanup, and manifest rewriting — but none of them run themselves. This guide covers why each operation matters, the correct execution order, the limitations of scripts and cron jobs, and how to automate the full lifecycle with policies, observability, and a purpose-built control plane.

Chris P
Chris P
21 min read
Apache Iceberg 1.11.0 What's New — Nessie mascot beside an iceberg with icons for performance, security, routing, and extensibility.
Apache IcebergLakehouseCompaction

Apache Iceberg 1.11.0 — What's New?

Apache Iceberg 1.11.0 lands V3 maturity with production-ready deletion vectors, a native Variant type for semi-structured data, server-side scan planning, built-in table encryption, and a pluggable File Format API that opens the door to next-generation storage formats.

Jonathan Saring
Jonathan Saring
10 min read
Iceberg Lakehouse with AI Agents: A Guide — AI agent robots navigating an Apache Iceberg lakehouse with analytics dashboards, AI brain, and governance shield icons, Build like Netflix subtitle
AIApache IcebergLakehouse

Iceberg Lakehouse with AI Agents: A Guide

AI agents are becoming primary consumers of Iceberg lakehouse data — querying tables iteratively, at high frequency, and without human review. This guide walks through the five components your infrastructure needs to support agentic workloads — MCP connectivity, guardrails, multi-engine routing, self-optimizing storage, and observability — and shows how LakeOps provides each one.

Jonathan Saring
Jonathan Saring
24 min read
Intelligent Lakehouse — Build like Netflix. LakeOps control plane with observability, optimization, policies, and routing over Spark, Trino, Presto, and BI/ML on Iceberg and S3. 10x query performance, up to 80% lower storage costs, reliable at massive scale, fully automated.
Apache IcebergData LakehouseLakeOps

Intelligent Lakehouse: Build Like Netflix

Netflix spent years building an intelligent lakehouse — Polaris for catalog management, Autotune for compaction, janitors for cleanup, and Metacat for observability. LakeOps lets every team build the same — and go beyond — in minutes. Here is what an intelligent lakehouse actually requires, and how LakeOps provides each component.

Jonathan Saring
Jonathan Saring
19 min read
AWS Glue Iceberg Optimization — an S3 bucket with scattered data objects funneled through an optimization lens into a geometric iceberg, with icons for Search, Analytics, and Tuning
Apache IcebergAWSCompaction

AWS Glue Iceberg Optimization: A Practical Guide

AWS Glue provides native Iceberg support for cataloging, ETL, and built-in table maintenance — but production lakehouses hit limitations fast. This guide covers Glue catalog configuration, ETL best practices, compaction tuning, common pitfalls, and how a dedicated control plane fills the operational gaps.

David W
David W
20 min read
Databricks to Iceberg smooth migration — Databricks and Apache Iceberg connected by a data bridge, with table data flowing into an open Iceberg lakehouse
DatabricksApache IcebergLakeOps

Databricks to Iceberg Smooth Migration

Databricks to Iceberg smooth migration opens a multi-engine lakehouse — not a platform exit. Databricks stays central for ML and Spark; Iceberg adds Trino, Snowflake, and open catalogs. Five tools: LakeOps, UC managed Iceberg, Delta UniForm, Spark, and Lakehouse Federation.

David W
David W
18 min read
Apache Iceberg with dbt Optimization — dbt logo above SQL model cards flowing through a transformation pipeline into a geometric iceberg, with chart and analytics icons
Apache IcebergdbtCompaction

Apache Iceberg with dbt: Optimization Guide

dbt transforms your data — but who maintains the Iceberg tables underneath? A practical guide to dbt adapters, incremental strategies, table properties, and the maintenance gap that every dbt + Iceberg team hits in production.

Rob M
Rob M
16 min read
Apache Iceberg Puffin Statistics — a puffin bird beside a statistics dashboard showing file counts, records, partitions, and data size, connected to a geometric iceberg
Apache IcebergLakeOpsAnalytics

Apache Iceberg Puffin Statistics: A Practical Guide

Puffin files store table-level statistics — NDV sketches and custom blobs — that query engines use for join ordering, split planning, and cost-based optimization. A practical guide to how they work, how to collect them, how they go stale, and how to keep them accurate at scale.

David W
David W
18 min read
Apache Iceberg Table Health and Maintenance — health score dashboard showing 92 Healthy with status indicators for Snapshots, Manifests, Delete Files, Orphan Files, and File Health beside a geometric iceberg
Apache IcebergCompactionObservability

Apache Iceberg Table Health and Maintenance: A Complete Guide

Iceberg tables degrade silently in production — small files multiply, snapshots accumulate, orphans waste storage, and manifests fragment. A comprehensive guide to the five maintenance operations, why sequencing matters, the metrics that reveal problems early, and how to automate the full lifecycle.

David W
David W
21 min read
Apache Iceberg on AWS S3 — architecture diagram showing Iceberg metadata layers, AWS services, and the data lakehouse stack
Apache IcebergData LakehouseAWS

Apache Iceberg on AWS S3: A Guide

Apache Iceberg on AWS S3 is the standard architecture for open lakehouses. This guide covers how Iceberg's metadata hierarchy maps to S3 objects, the AWS services ecosystem (Glue, Athena, EMR, Redshift, S3 Tables), configuration best practices, performance optimization, table maintenance, and the operational components needed for production deployments.

Rob M
Rob M
24 min read
Snowflake to Iceberg migration — Snowflake tables flowing into an Apache Iceberg lakehouse, illustrating a hybrid multi-engine architecture where Snowflake remains a valued component
SnowflakeApache IcebergLakeOps

Snowflake to Iceberg Smooth Migration

A practical guide for senior data engineers expanding Snowflake into a multi-engine Iceberg lakehouse. Covers five production tools — LakeOps, managed Iceberg, Open Catalog sync, Spark, and AWS Glue — with migration patterns, operational trade-offs, and a phased rollout sequence.

David W
David W
17 min read
Annual cloud bill infographic showing Iceberg lakehouse spend doubling year over year — FinOps and cost reduction framing for data platform teams in 2026
FinOpsApache IcebergLakeOps

State of Iceberg FinOps and Cost Reduction in 2026

State of Iceberg FinOps in 2026: where lakehouse spend leaks, what to measure, how autonomous management and optimization are replacing manual maintenance — and a practical survey of tools from cloud optimizers to control planes.

David W
David W
24 min read
Diagram showing seven Iceberg catalog options — Polaris, Nessie, Glue, Unity, Gravitino, Lakekeeper, and Hive — connected to a central Apache Iceberg symbol
Apache IcebergLakehouseData Lake

Best Catalog for Apache Iceberg? A Useful Comparison

A technical comparison of the seven major Apache Iceberg catalogs — Hive Metastore, AWS Glue, Apache Polaris, Project Nessie, Databricks Unity Catalog, Apache Gravitino, and Lakekeeper — across protocol support, access control, multi-engine interoperability, credential vending, and production readiness.

Chris P
Chris P
21 min read
Iceberg Lake for Data Analytics: Optimization Guide — iceberg on water with analytics dashboard showing 9.4× query speed, 68% cost efficiency gain, and 82% less data scanned
Apache IcebergData PlatformsData Lake

Iceberg Lake for Data Analytics: Optimization Guide

Eight optimization layers for data platform engineers running BI, ad-hoc SQL, and aggregation pipelines on Apache Iceberg — from partition design and file sizing through compaction, routing, and continuous maintenance.

Jonathan Saring
Jonathan Saring
15 min read
LakeOps Data Lake Insights showing metadata health alerts across Iceberg tables — manifest fragmentation, snapshot accumulation, and partition skew
Apache IcebergData PlatformsData Lake

Iceberg Metadata Lifecycle: Maintenance and Optimization

A deep technical guide to managing the metadata layer that makes Apache Iceberg fast — snapshots, manifests, metadata.json files, and Puffin statistics — covering expiration, consolidation, orphan cleanup, and the sequencing that prevents production incidents.

Jonathan Saring
Jonathan Saring
19 min read
Iceberg lakehouse cost reduction — cost waste flows through LakeOps autonomous operations to deliver 80% savings
Apache IcebergLakeOpsCloud Cost

7 Iceberg Lakehouse Cost Reduction Strategies

Iceberg lakehouses silently accumulate cost from small files, dead snapshots, orphan data, unoptimized layouts, and over-provisioned compute. Seven practical strategies — from deploying an autonomous control plane to leveraging partition evolution — that production data teams use to cut lakehouse spend by up to 80%.

Jonathan Saring
Jonathan Saring
9 min read
Optimizing Iceberg Lakehouse Performance — problems (small files, fragmented manifests, unsorted data, delete files) flow through autonomous maintenance into faster queries, lower costs, higher throughput, and healthier data
Apache IcebergLakeOpsAnalytics

Optimizing Iceberg Lakehouse Performance

Iceberg tables degrade silently — small files from streaming, unsorted data, fragmented manifests, accumulated delete files. Each one caps query speed regardless of engine. Six concrete optimization layers, how they interact, and how autonomous maintenance keeps every table at peak performance.

David W
David W
11 min read
Data Lake vs Lakehouse vs Warehouse: A Practical Guide — watercolor illustration comparing a natural data lake (raw flexible storage), a lakehouse (open storage with analytics on the water), and a data warehouse (structured BI building with charts in the windows)
Data PlatformsData LakeLakehouse

Data Lake vs Lakehouse vs Warehouse: A Practical Guide

Data lakes, warehouses, and lakehouses are not interchangeable — each has hard limits the others cannot cover. A practical guide for platform leaders: where each architecture wins, where it fails, cost and governance trade-offs, and how to choose (or combine) them in 2026.

Chris P
Chris P
22 min read
Iceberg Table Maintenance Solution Comparison — side-by-side feature matrix for LakeOps, AWS Glue, S3 Tables, Snowflake, BigLake, Cloudera, and Starburst
CompactionData LakehouseApache Iceberg

9 Iceberg Table Compaction Tools Compared for Production Lakehouses

Compaction keeps Apache Iceberg lakehouses fast and lean — but every tool approaches it differently. A side-by-side look at nine production options: LakeOps, AWS Glue, Amazon S3 Tables, Snowflake, Google BigLake, Cloudera, Starburst, Dremio, and Databricks.

Jonathan Saring
Jonathan Saring
18 min read
LakeOps lakehouse control plane — connected to Iceberg catalogs on the left, query engines on the right, with observability, autonomous optimization, and cost management in the center
Apache IcebergLakeOpsLakehouse

Iceberg Lakehouse Optimization with LakeOps

A practical walkthrough of optimizing an Apache Iceberg lakehouse end to end — from connecting catalogs and diagnosing table health through autonomous compaction, lifecycle management, and multi-engine routing to measurable cost and performance outcomes.

Rob M
Rob M
16 min read
From data swamp to modern Iceberg lakehouse — illustrated journey from scattered files and broken schemas through Apache Iceberg to a managed lakehouse with a control plane
Data PlatformsData LakehouseApache Iceberg

From Data Swamp to Modern Iceberg Lakehouse

Every data lake starts with a promise of unlimited flexibility — and most end up as a swamp. Stale files, broken schemas, no observability, and engineers spending more time maintaining pipelines than analyzing data. Apache Iceberg fixed the reliability gap. A lakehouse control plane fixes everything else. A practical guide to the full transition — component by component.

Jonathan Saring
Jonathan Saring
23 min read
Optimizing Iceberg Lake Compaction — scattered small data-block cubes funnel through a compaction machine onto a conveyor belt of optimized blocks, leading to a crystal-clear iceberg lakehouse
CompactionApache IcebergLakehouse

Optimizing Iceberg Lake Compaction: A Guide

Compaction is the most impactful operation in an Apache Iceberg lakehouse — and the hardest to get right at scale. File merging is the easy part. Knowing when to trigger it, what sort strategy to apply per table, how to avoid conflicting with other maintenance, and how to do it without spinning up expensive JVM clusters — that is the real problem. A breakdown of what modern compaction actually requires.

Jonathan Saring
Jonathan Saring
17 min read
Iceberg lakehouse optimization — multi-engine ecosystem (AWS, Databricks, Trino, DuckDB, Snowflake, Flink, and more) around a shared Iceberg lake, with observability and optimization above the waterline
Apache IcebergLakehouseLakeOps

Iceberg Lakehouse Optimization — The Right Way

Apache Iceberg gives your lakehouse warehouse-grade reliability on object storage — but the format does not optimize itself. A practical guide to every operational pillar a production Iceberg lakehouse needs — from lake-wide observability and query-aware compaction to snapshot lifecycle, metadata health, and governance — and how LakeOps runs it all from a single control plane.

Jonathan Saring
Jonathan Saring
21 min read
LakeOps table metrics showing records distribution, file size distribution, and table size growth over the last 30 days
Apache IcebergLakeOpsFinOps

Autonomous Iceberg Table Maintenance for Data Lakes

Iceberg tables need continuous maintenance — compaction, snapshot expiration, manifest optimization, and orphan cleanup — but manual scripts break at scale. A deep look at what autonomous table maintenance means in practice: how telemetry-driven orchestration replaces reactive firefighting and keeps every table healthy without human intervention.

Rob M
Rob M
16 min read
Modern lakehouse architecture: LakeOps control plane for autonomous management and optimization — observability, compaction, routing, AI guardrails, and governance above Iceberg on S3, with catalogs and multi-engine compute (Spark, Trino, Snowflake, Databricks, and more)
Data PlatformsApache IcebergSnowflake

From Databricks and Snowflake to an Open Data Platform

For a decade, Snowflake and Databricks defined enterprise data. Then the lakehouse emerged — open formats on open storage. What was missing was the operational layer to make it work at scale. An autonomous control plane turns a lakehouse into a managed open data platform — without the lock-in.

Jonathan Saring
Jonathan Saring
18 min read
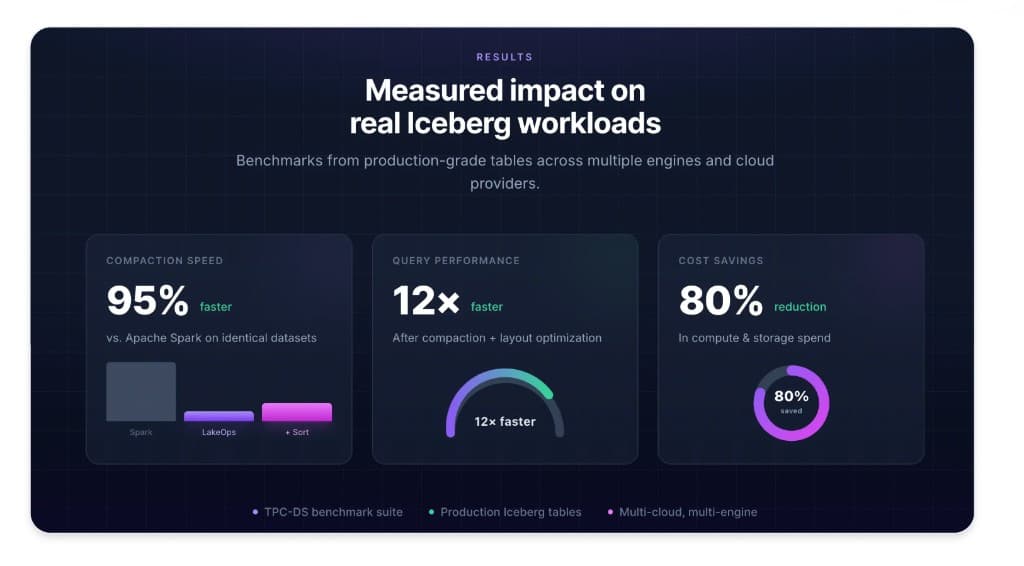
LakeOps measured results on production Iceberg workloads: 95% faster compaction, 12x query performance improvement, 80% cost reduction
Apache IcebergLakeOpsCloud Cost

Apache Iceberg Cost Optimization in 2026

Your Iceberg lake is overcharging you from four directions at once — storage bloat, query compute waste, compaction overhead, and engineering time. This post breaks down exactly where each dollar goes and how autonomous table management eliminates the waste without touching your pipelines.

David W
David W
22 min read
LakeOps control plane for AI agents — MCP, guardrails, routing, storage optimization, observability, and workload policies above Iceberg tables on object storage
AIApache IcebergLakeOps

Optimizing Apache Iceberg for Agentic AI: From Slow Tables to Sub-Second Agent Queries

AI agents issue SQL iteratively, repeat query templates at high frequency, and need sub-second responses from tables designed for batch workloads. This post covers what breaks when agents hit a production Iceberg lake — and the five infrastructure layers that fix it: MCP connectivity, guardrails, multi-engine routing, self-optimizing storage, and closed-loop feedback.

Chris P
Chris P
18 min read
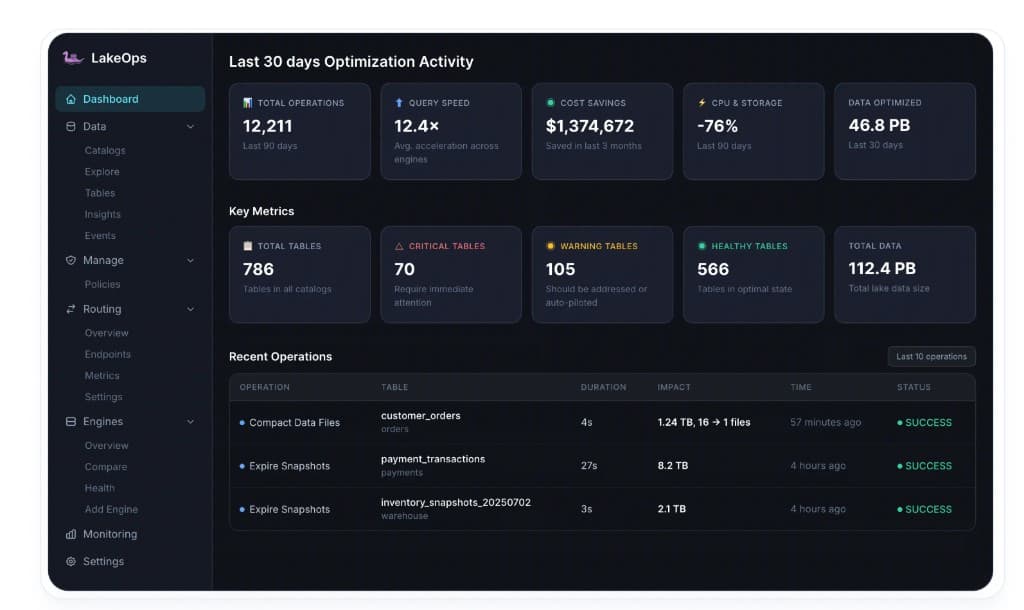
LakeOps dashboard showing optimization activity, key metrics, and recent operations across production Iceberg tables
Apache IcebergData LakehouseLakeOps

Managed Iceberg in 2026: Autonomous Data Lake

Iceberg tables degrade silently — small files pile up, snapshots bloat metadata, and query latency creeps higher. A breakdown of the nine components every production data lake needs to stay healthy — starting with observability and telemetry collection, through compaction, snapshot management, and lake-wide policies, to multi-engine routing and agentic AI enablement.

Jonathan Saring
Jonathan Saring
23 min read
Introducing QueryFlux: Open-Source Universal Multi-Engine Query Router and SQL Proxy
QueryFluxApache IcebergData Platforms

Introducing QueryFlux: Open-Source Universal Multi-Engine Query Router and SQL Proxy

QueryFlux is a universal SQL proxy and multi-engine query router in Rust—one access layer in front of Trino, DuckDB, StarRocks, and Athena with routing, dialect translation, and observability.

Jonathan Saring
Jonathan Saring
12 min read
Cracking the Ice: The Battle Between Sort and Binpack in Apache Iceberg
Apache IcebergCompactionData Platforms

Cracking the Ice: The Battle Between Sort and Binpack in Apache Iceberg

Unlocking performance vs. optimizing storage — choosing the right compaction strategy for your data lake.

LakeOps Team
LakeOps Team
7 min read
Delta Lake vs Apache Iceberg: Choosing the Right Table Format
Delta LakeApache IcebergData Lake

Delta Lake vs Apache Iceberg: Choosing the Right Table Format

A detailed comparison between Delta Lake and Apache Iceberg, exploring their architectures, performance characteristics, and ideal use cases to help you make the right choice.

LakeOps Team
LakeOps Team
10 min read
Incremental Processing with Apache Iceberg & Spark: A Comprehensive Guide
Apache IcebergApache SparkData Platforms

Incremental Processing with Apache Iceberg & Spark: A Comprehensive Guide

Learn how to implement efficient incremental processing with Apache Iceberg and Spark, including best practices for data lake optimization and performance tuning.

LakeOps Team
LakeOps Team
9 min read