Back to all articles

QueryFlux articles

Guides and updates on QueryFlux, the open-source SQL query engine for federated data access across lakehouses.

10 articles

Snowflake to Iceberg lakehouse migration: tables flowing from a Snowflake warehouse into an Apache Iceberg lakehouse on open storage
SnowflakeApache IcebergData Lakehouse

Snowflake to Iceberg Lakehouse Migration Guide

Moving from Snowflake to an Apache Iceberg lakehouse is not a data copy. Snowflake bundles storage, catalog, compute, and operations into one product; Iceberg hands each one back to you. This guide walks the migration phase by phase — inventory, catalog ownership, type translation, data movement, pipelines, workloads, and governance — and shows where a control plane replaces the operations Snowflake used to run invisibly.

Rob M
Rob M
26 min read
Offload Snowflake Queries Without Changing Clients
QueryFluxSnowflakeCloud Cost

Offload Snowflake Queries Without Changing Clients

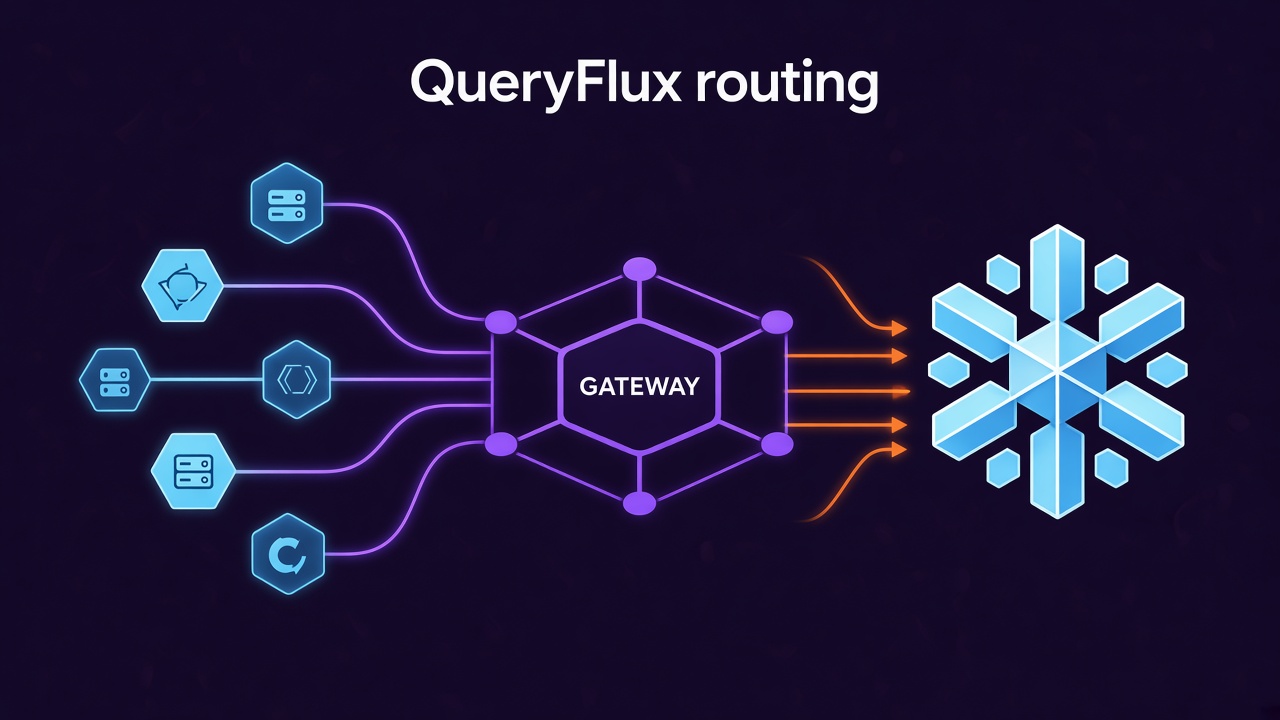
Point Snowflake clients at QueryFlux, keep heavy work on Snowflake, and offload the rest to Trino or StarRocks — no dashboard or notebook rewrites.

Amit Gilad
Amit Gilad
4 min read
One Endpoint for Apache Iceberg on Trino and StarRocks
QueryFluxApache IcebergTrino

One Endpoint for Apache Iceberg on Trino and StarRocks

Run Trino and StarRocks on the same Iceberg tables behind one QueryFlux SQL endpoint — route BI and notebooks without client rewrites.

Amit Gilad
Amit Gilad
5 min read
Give AI Agents SQL, Not the Keys to Every Engine
QueryFluxAIData Governance

Give AI Agents SQL, Not the Keys to Every Engine

Put AI agents behind QueryFlux — one MCP or SQL endpoint with routing, guardrails, impersonation, and a record of every query.

Amit Gilad
Amit Gilad
6 min read
Why QueryFlux: The Missing Layer Above Query Engines
QueryFluxData PlatformsApache Iceberg

Why QueryFlux: The Missing Layer Above Query Engines

Open table formats made data interoperable. Query engines are still islands. Why QueryFlux exists as a neutral SQL layer above the engines.

Amit Gilad
Amit Gilad
8 min read
The Future Isn't One Engine — Spark, Trino, DuckDB, Snowflake, Flink, and StarRocks connected through an intelligent control plane above an Apache Iceberg lakehouse
Data PlatformsApache IcebergLakehouse

The Future Isn't One Engine. It's a Control Plane.

The future of data platforms isn't one engine. It's specialized engines on shared data, and a control plane that decides where each workload runs and how the tables stay fast.

Amit Gilad
Amit Gilad
10 min read
Iceberg Lakehouse with AI Agents: A Guide — AI agent robots navigating an Apache Iceberg lakehouse with analytics dashboards, AI brain, and governance shield icons, Build like Netflix subtitle
AIApache IcebergLakehouse

Iceberg Lakehouse with AI Agents: A Guide

AI agents are becoming primary consumers of Iceberg lakehouse data — querying tables iteratively, at high frequency, and without human review. This guide walks through the five components your infrastructure needs to support agentic workloads — MCP connectivity, guardrails, multi-engine routing, self-optimizing storage, and observability — and shows how LakeOps provides each one.

Jonathan Saring
Jonathan Saring
24 min read
Multiple Query Engines with Iceberg — Ferris the Rust crab routing queries to Trino, Snowflake, DataFusion, Databricks, Presto, ClickHouse, DuckDB, and Apache Spark over an Iceberg Lakehouse
Apache IcebergData LakehouseQueryFlux

Routing Multiple Query Engines with Iceberg

How to route queries across Trino, Spark, DuckDB, Snowflake, Athena, and Flink on shared Iceberg tables — covering the architecture of a SQL routing proxy, dialect translation, routing strategies, table-aware optimization, and the tooling that makes it work.

Rob M
Rob M
18 min read
LakeOps control plane for AI agents — MCP, guardrails, routing, storage optimization, observability, and workload policies above Iceberg tables on object storage
AIApache IcebergLakeOps

Optimizing Apache Iceberg for Agentic AI: From Slow Tables to Sub-Second Agent Queries

AI agents issue SQL iteratively, repeat query templates at high frequency, and need sub-second responses from tables designed for batch workloads. This post covers what breaks when agents hit a production Iceberg lake — and the five infrastructure layers that fix it: MCP connectivity, guardrails, multi-engine routing, self-optimizing storage, and closed-loop feedback.

Chris P
Chris P
18 min read
Introducing QueryFlux: Open-Source Universal Multi-Engine Query Router and SQL Proxy
QueryFluxApache IcebergData Platforms

Introducing QueryFlux: Open-Source Universal Multi-Engine Query Router and SQL Proxy

QueryFlux is a universal SQL proxy and multi-engine query router in Rust—one access layer in front of Trino, DuckDB, StarRocks, and Athena with routing, dialect translation, and observability.

Jonathan Saring
Jonathan Saring
12 min read