Back to all articles

AWS articles

AWS data lake services — S3, Glue, Athena, EMR, Lake Formation, and Apache Iceberg integration on Amazon Web Services.

13 articles

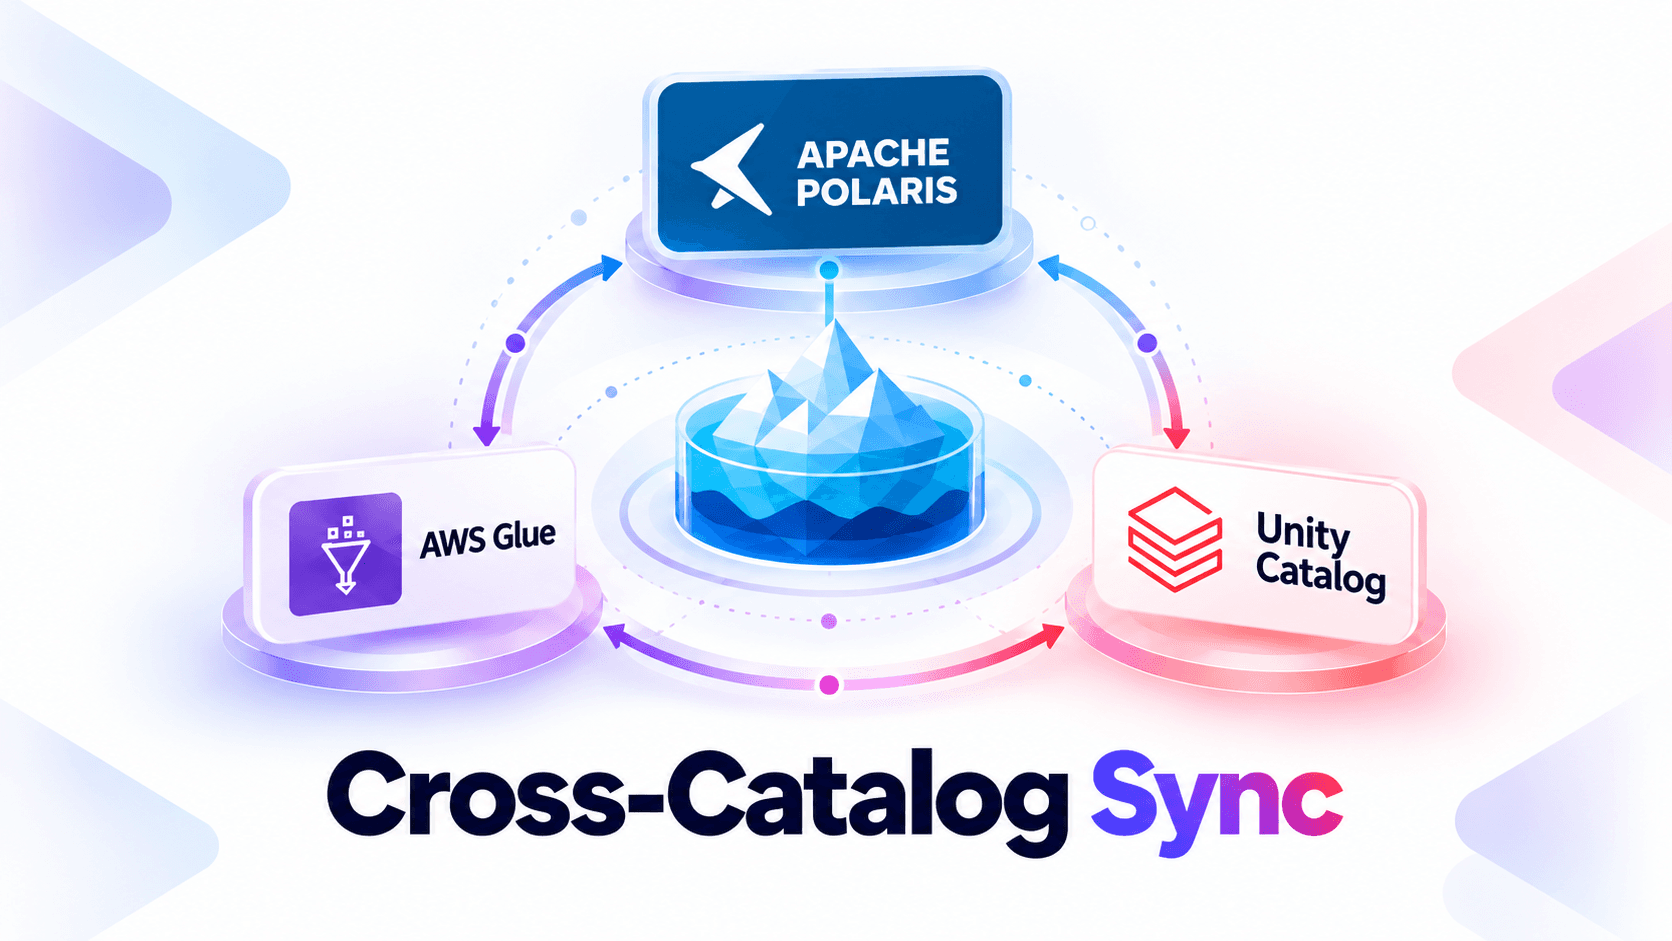
Cross-catalog sync between Apache Polaris, AWS Glue, and Databricks Unity Catalog over shared Apache Iceberg tables
Data PlatformsApache IcebergDatabricks

Cross-Catalog Sync: Iceberg on Polaris, Glue, and Unity

Three Iceberg catalogs, one lake, and no single operational view. Why bidirectional catalog sync is a correctness bug, how federation actually works across Polaris, Glue, and Unity Catalog, and how to run one operating model over catalogs that will never merge.

Chris P
Chris P
27 min read
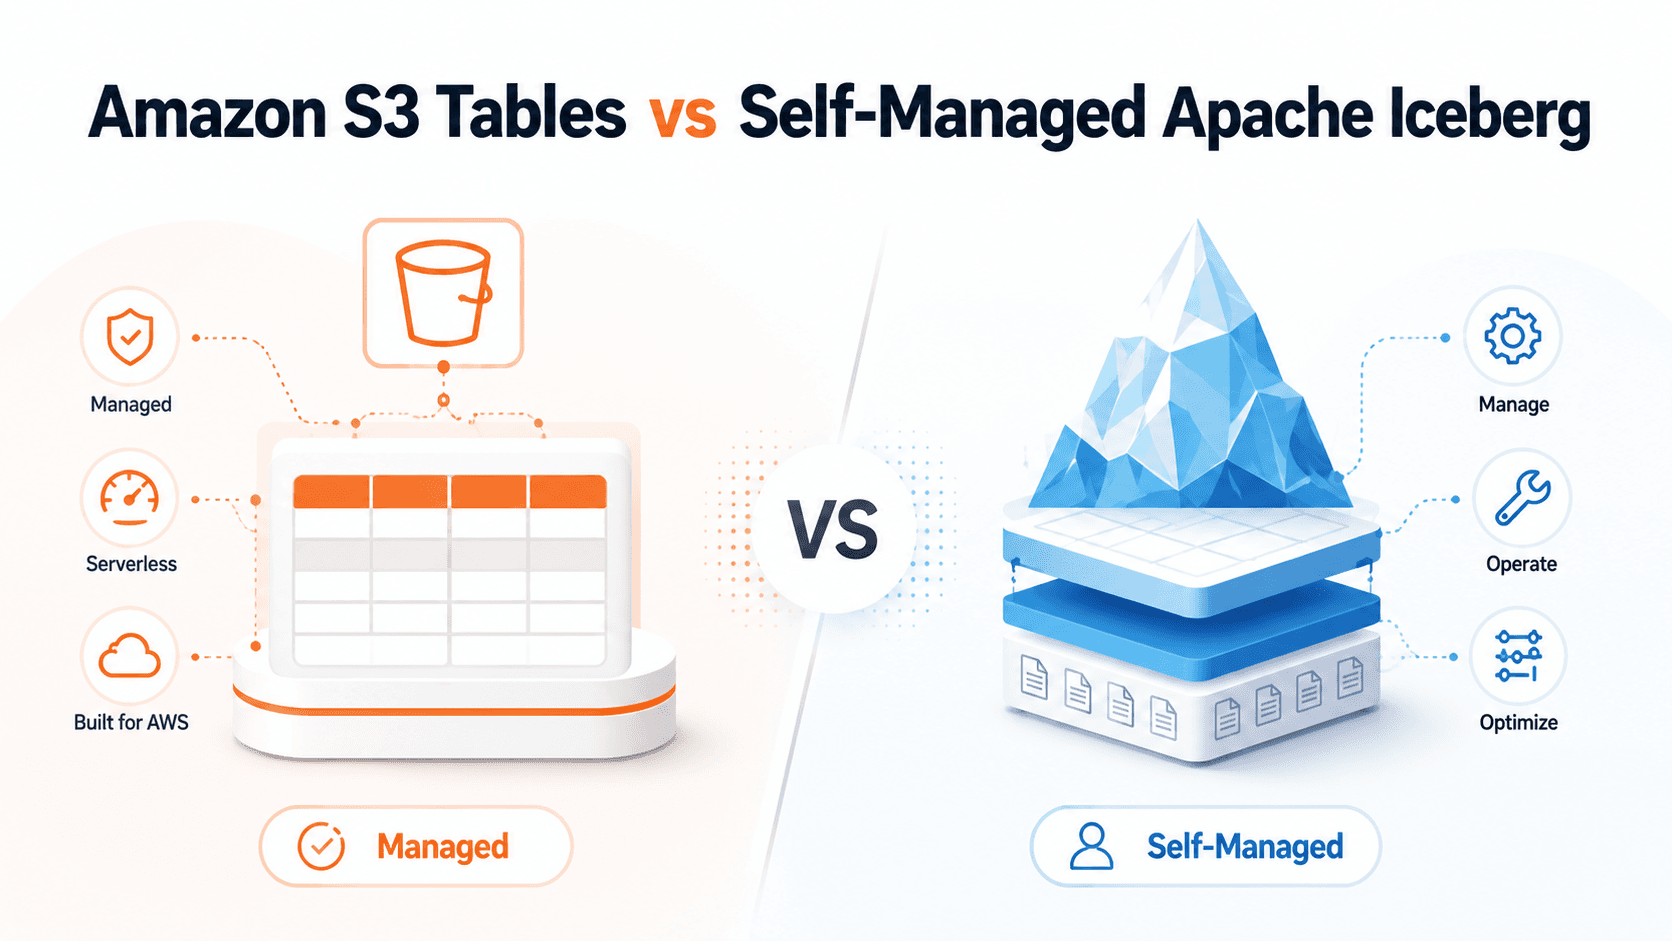
Amazon S3 Tables vs Self-Managed Apache Iceberg architecture comparison on AWS
Apache IcebergData LakehouseAWS

Amazon S3 Tables vs Self-Managed Iceberg

S3 Tables embeds managed Iceberg into S3 with automatic compaction. Self-managed Iceberg gives full control over catalogs, engines, and maintenance. A production comparison across compaction, observability, engine support, security, cost, and the control plane that ties it all together.

Rob M
Rob M
21 min read
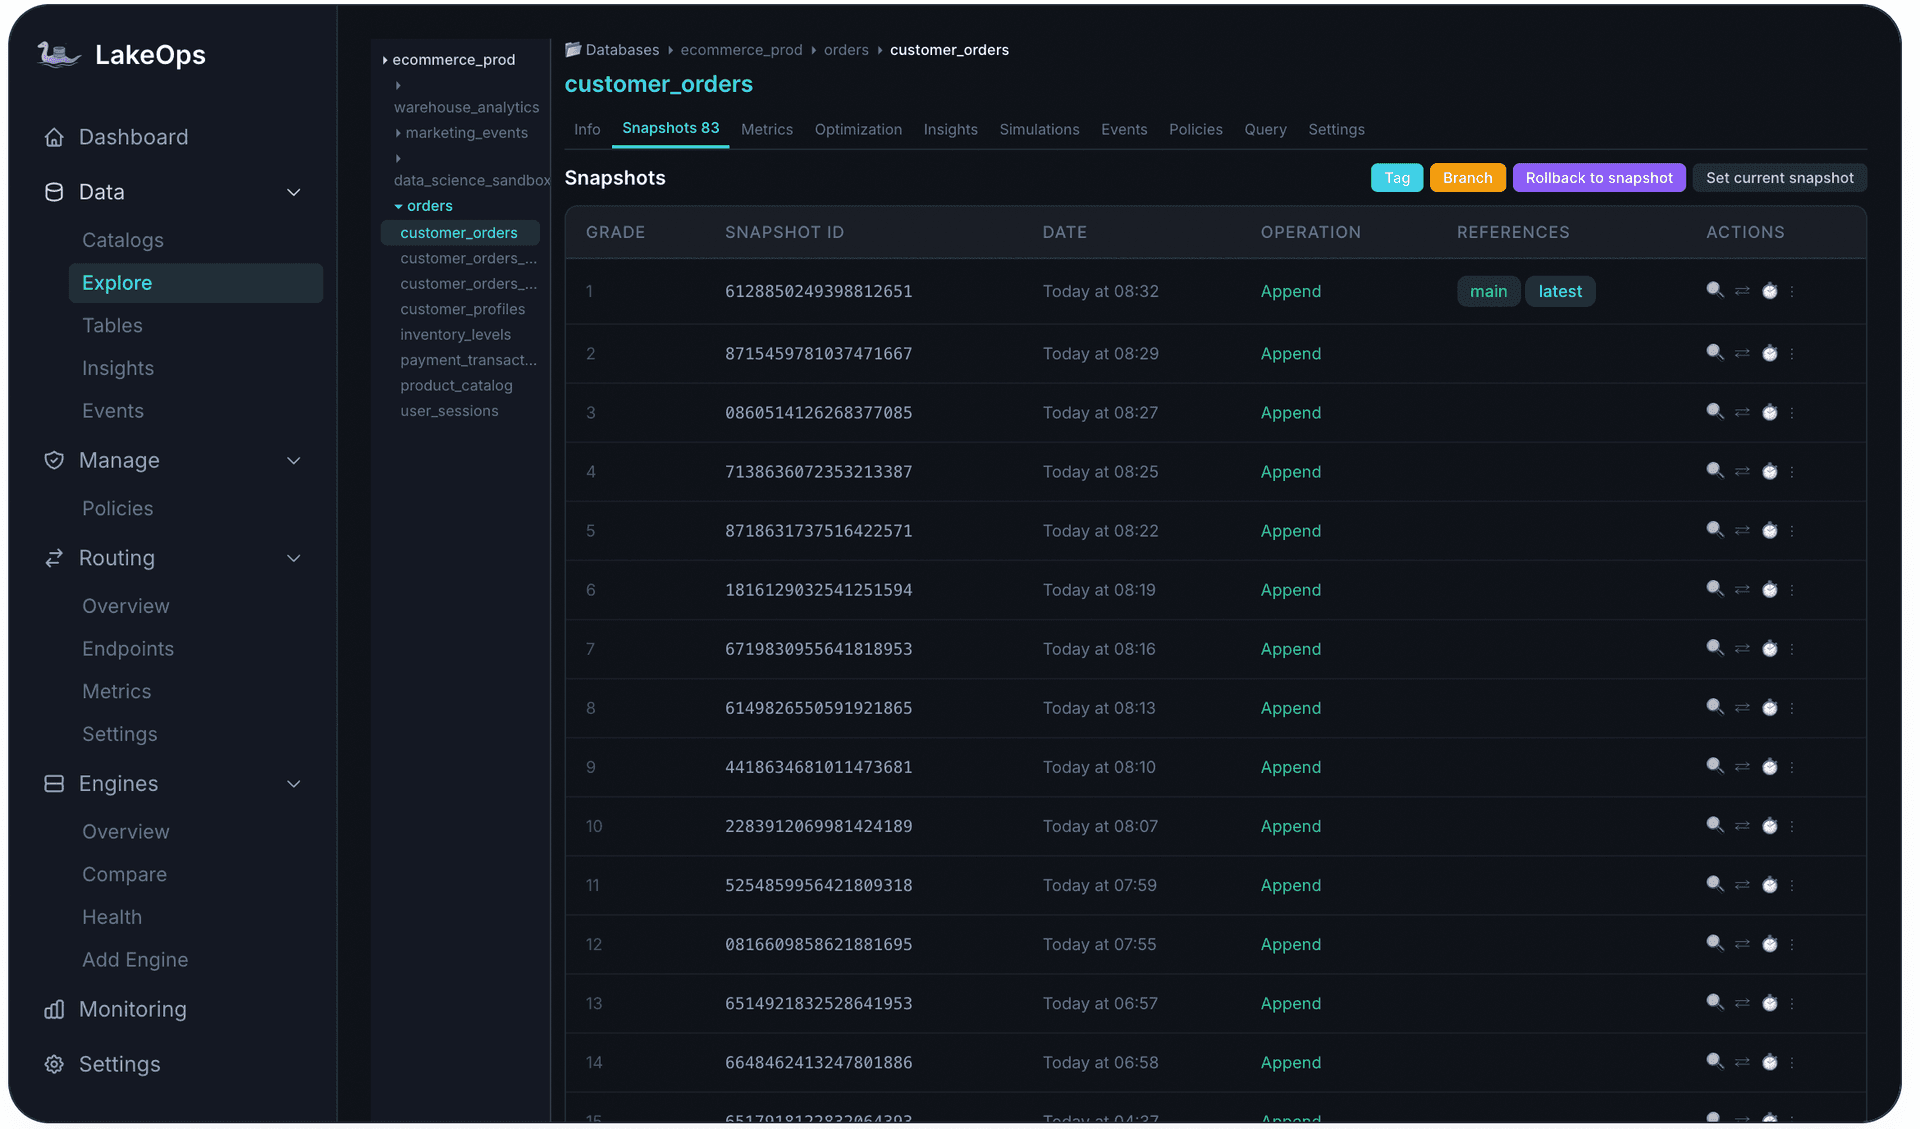
LakeOps snapshot management — table snapshots list with time travel, rollback, and retention controls
Apache IcebergLakeOpsData Lake

Snapshot Retention and Time Travel: A Guide

Iceberg snapshots enable time travel, rollback, and audit — but accumulate indefinitely unless managed. A practical guide to retention strategies, expiration safety, and automated lifecycle management.

Rob M
Rob M
11 min read
Apache IcebergLakeOpsAWS

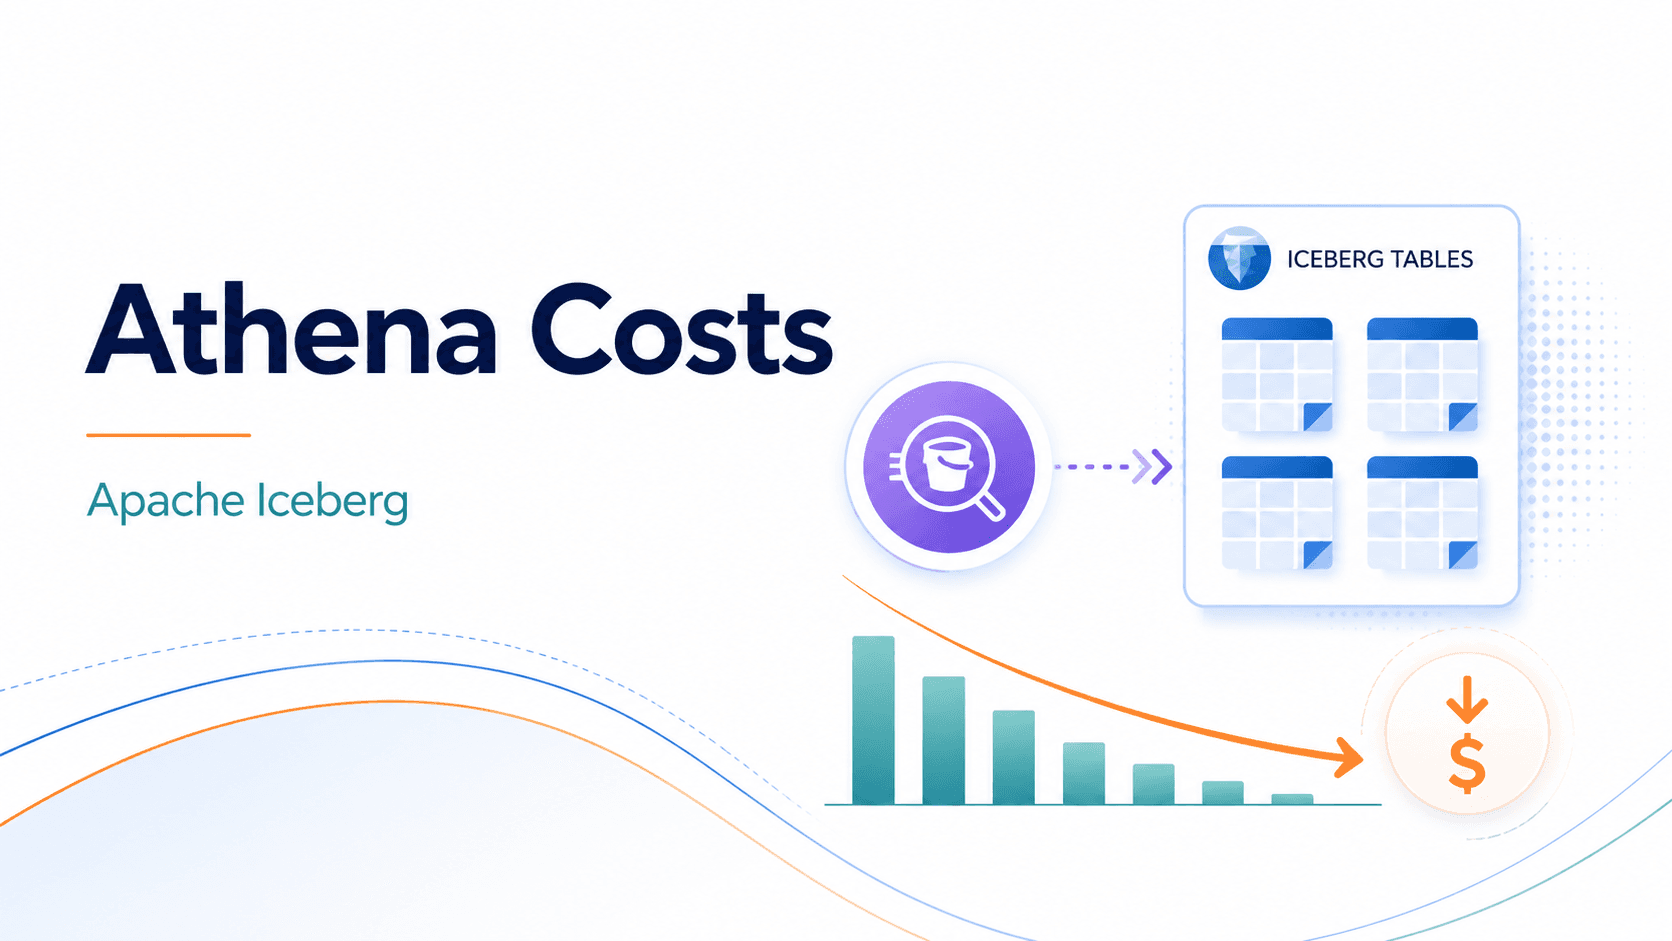
Reduce Amazon Athena Costs on Apache Iceberg Tables

Athena charges $5 per TB scanned — and on poorly maintained Iceberg tables, every query scans far more data than it should. This guide breaks down why Athena bills explode on Iceberg (small files, bad sort order, stale manifests, scan amplification) and presents two paths to fix it: autonomous optimization with LakeOps or the manual approach with Athena SQL and Spark.

Chris P
Chris P
20 min read
Apache Iceberg at scale — infrastructure, performance, and enterprise lessons
Apache IcebergData PlatformsLakeOps

Apache Iceberg at Scale: Infrastructure, Performance, and Enterprise Lessons

Running Iceberg at 10 tables is configuration. Running it at 10,000 is infrastructure. Production lessons on infrastructure evolution, Parquet tuning, Spark configuration, catalog scaling, enterprise security, and observability-driven optimization for production Iceberg deployments.

David W
David W
33 min read
Zero-trust data architecture for AI workloads on Apache Iceberg and S3
Data PlatformsApache IcebergData Governance

Zero-Trust Data Architecture for AI Workloads on Apache Iceberg and S3

AI workloads running against Iceberg tables on S3 need more than fast queries — they need provably secure, least-privilege access to every byte they touch. This article walks through a zero-trust data architecture built on vended credentials, the Iceberg REST catalog, and Kubernetes-native orchestration — replacing static keys with short-lived, table-scoped tokens enforced at the storage layer.

Rob M
Rob M
32 min read
Apache Iceberg Migration Strategy — from Hive, Parquet, or Delta to production Iceberg
Data PlatformsApache IcebergDelta Lake

Apache Iceberg Migration Strategy: From Hive, Parquet, or Delta to Production Iceberg

A comprehensive migration guide covering three source patterns — Hive/HMS tables, raw Parquet on S3, and Delta Lake — with three migration approaches (in-place, CTAS, shadow), post-migration operations, validation checklists, and common pitfalls. Includes production SQL, config examples, and the operational discipline teams underestimate after conversion.

Jonathan Saring
Jonathan Saring
33 min read
Apache Iceberg Catalog Migration — Hive Metastore to REST, Polaris, Glue, or Nessie
Apache IcebergData PlatformsLakeOps

Apache Iceberg Catalog Migration: Hive Metastore to REST, Polaris, Glue, or Nessie

A practical guide for migrating Apache Iceberg catalogs — from Hive Metastore to REST (Polaris, Gravitino), AWS Glue, Nessie, or Unity Catalog. Covers in-place metadata registration, dual-catalog access, validation, rollback strategies, and multi-catalog federation with LakeOps.

Chris P
Chris P
30 min read
Apache Iceberg Orphan Files — safe cleanup without breaking tables, with shield and broom icons over an Iceberg table
Apache IcebergCloud CostLakeOps

Apache Iceberg Orphan Files: Safe Cleanup Without Breaking Tables

Orphan files are invisible to Iceberg but fully billable by cloud storage. They accumulate silently from failed writes, crashed compaction, and concurrent conflicts — and on mature lakes they can account for 25–40% of storage spend. This guide covers how orphan files are created, how to detect them safely, the retention window that prevents table corruption, and how to automate cleanup at lake scale without listing millions of objects.

David W
David W
26 min read
AWS Glue Iceberg Optimization — an S3 bucket with scattered data objects funneled through an optimization lens into a geometric iceberg, with icons for Search, Analytics, and Tuning
Apache IcebergAWSCompaction

AWS Glue Iceberg Optimization: A Practical Guide

AWS Glue provides native Iceberg support for cataloging, ETL, and built-in table maintenance — but production lakehouses hit limitations fast. This guide covers Glue catalog configuration, ETL best practices, compaction tuning, common pitfalls, and how a dedicated control plane fills the operational gaps.

David W
David W
20 min read
Apache Iceberg on AWS S3 — architecture diagram showing Iceberg metadata layers, AWS services, and the data lakehouse stack
Apache IcebergData LakehouseAWS

Apache Iceberg on AWS S3: A Guide

Apache Iceberg on AWS S3 is the standard architecture for open lakehouses. This guide covers how Iceberg's metadata hierarchy maps to S3 objects, the AWS services ecosystem (Glue, Athena, EMR, Redshift, S3 Tables), configuration best practices, performance optimization, table maintenance, and the operational components needed for production deployments.

Rob M
Rob M
24 min read
Reducing AWS S3 cost with Apache Iceberg — diagram showing S3 storage and API cost vectors from Iceberg write patterns and the optimization strategies that address them
FinOpsApache IcebergAWS

Reducing AWS S3 Cost with Iceberg: A Guide

AWS S3 bills for Iceberg lakehouses are inflated by small files, orphan data, retained snapshots, metadata overhead, and scan amplification. This guide quantifies each cost vector with S3 pricing mechanics and walks through five strategies — compaction, expiration, layout optimization, storage tiering, and engine routing — to cut storage and query spend.

Rob M
Rob M
21 min read
From 350TB to 230TB in 10 Minutes: The Hidden Weight of Stale Data
Apache IcebergData LakeLakeOps

From 350TB to 230TB in 10 Minutes: The Hidden Weight of Stale Data

See how a 350TB data lake shrank to 230TB in 10 minutes by removing stale data—saving 34% in AWS S3 costs and proving the need for a control plane.

LakeOps Team
LakeOps Team
5 min read